Posted on — 1 Comment

Adaptive Learning in Primary Maths: What 7,885 Pupils Show

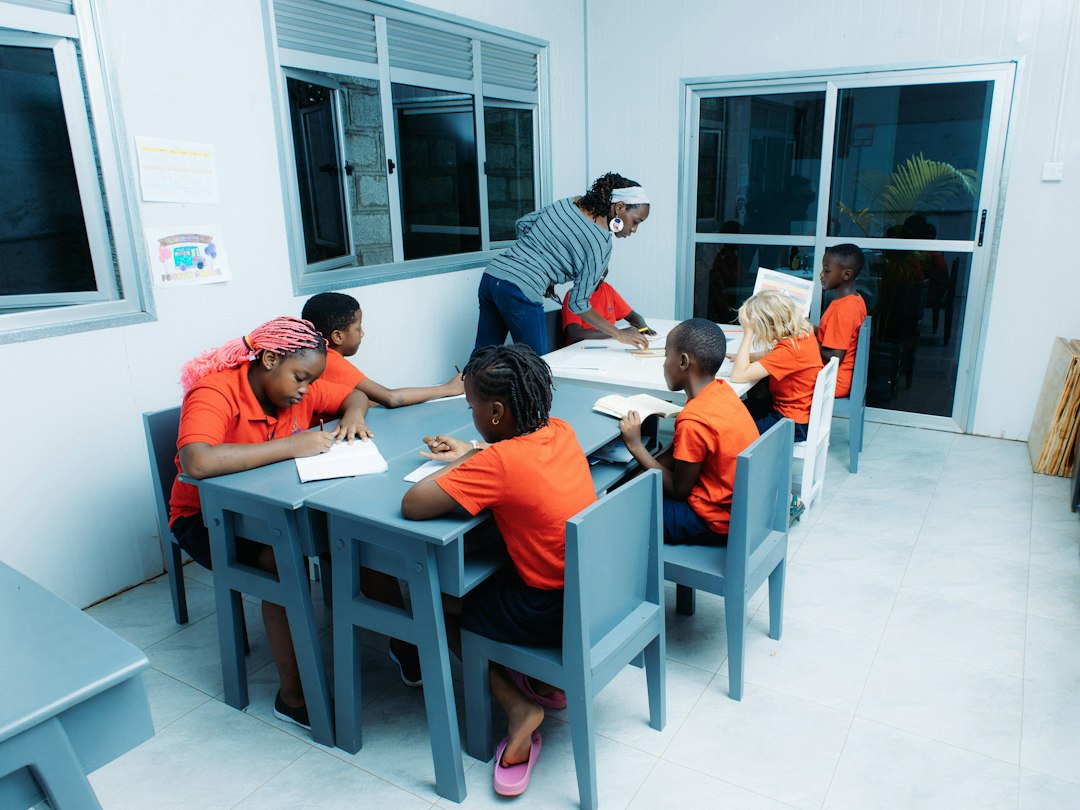
Primary-school pupils working on mathematics activities with a teacher nearby

Research update — 23 October 2026. Adaptive learning in primary maths is often promoted as a way to personalise practice for every child. A research update from Radboud University on 2 October reported a large, multi-year study of 7,885 Dutch primary-school pupils: children using an adaptive learning system showed slightly more positive growth in mathematics performance than peers in classes that did not use it. The result is encouraging, but its limits matter just as much as the headline.

The key lesson is not that software can replace a teacher. It is that adaptive practice may help teachers respond to differences between learners—when it is connected to a clear curriculum, interpreted by educators, and evaluated through learning rather than screen activity.

What did the 7,885-pupil study find?

According to Radboud University’s research summary, researchers examined the development of numeracy skills among 7,885 Dutch primary-school pupils over a three-year period. The data covered the years 2014–2017, when classes using an adaptive learning system were compared with classes teaching mathematics without that system.

The software adjusted the difficulty of exercises in response to pupils’ performance: learners doing well received more challenging tasks, while those struggling received simpler ones. The university reported a small, generally positive trend in maths growth. The effects appeared more evident in larger schools and in schools serving more socio-economically disadvantaged pupils, where differences in prior attainment may be harder for one teacher to address simultaneously.

The study is reported as Arithmetic Development: A Longitudinal Observational Study into the Use of Adaptive Technology, listed by the university as forthcoming in Learning and Instruction. The important distinction is methodological: this was a longitudinal observational study, not a randomised trial. It can identify a pattern across a large sample, but it cannot by itself establish that the software caused every difference observed.

Why “adaptive learning” is not the same as a chatbot

Searches for AI learning tools often group very different technologies together. An adaptive maths platform typically selects or adjusts practice tasks using a learner’s answers and progress data. A generative AI chatbot produces new explanations or responses in natural language. Some products combine both, but the evidence for one type should not automatically be treated as evidence for the other.

The Dutch study examined adaptive learning technology used in 2014–2017—well before today’s generative AI chatbots became widely available. It therefore offers useful evidence about personalised practice and learner progression, but it does not demonstrate that a conversational AI tutor improves maths learning. For a separate discussion of how to judge education tools, see our guide to evaluating AI learning tools in schools.

What the findings mean for primary-school teachers

1. Use software to target practice, not to define the curriculum

Adaptive systems can vary the pace and difficulty of practice, but teachers still need to decide which mathematical ideas pupils should understand. A platform’s next-task recommendation is not a substitute for curriculum sequencing, classroom discussion, or professional judgement. Before adopting a tool, map its activities to the learning objectives and identify which concepts require direct explanation or concrete materials.

2. Ask pupils to explain their reasoning

Correct answers alone do not reveal whether a child understands place value, has memorised a procedure, or guessed successfully. Pair digital practice with brief explanations: “How did you work it out?”, “Why does this answer make sense?”, or “Can you show another method?” Teachers can use recurring errors as prompts for a small-group lesson instead of assuming that a progress dashboard tells the whole story.

3. Check transfer away from the platform

Improvement inside an app is not necessarily the same as durable learning. Periodically give pupils a short, curriculum-aligned task on paper or at the board, without hints from the software. Include a new problem that requires the same underlying idea in a different form. If performance drops sharply when the tool is removed, the next step may be more explanation and guided practice—not simply more app time.

4. Keep the teacher in the feedback loop

The Radboud report explicitly stresses the continuing role of teachers. A useful workflow is to review the platform’s error patterns, compare them with classwork, select one misconception to address, and then check whether pupils can apply the correction independently. Automated feedback can make practice more responsive, but it may not reveal language difficulties, anxiety, gaps in prior knowledge, or the reason a child chose an answer.

5. Test whether the tool is equitable in your setting

The reported stronger pattern in larger and more disadvantaged schools is worth investigating, not a guarantee that every under-resourced school will benefit. Schools should check device availability, connectivity, accessibility, language support, and whether the tasks reflect pupils’ curriculum and context. Ask which learner data are collected, how long they are retained, who can access them, and whether teachers can export or delete them under the school’s policies.

How schools can evaluate an adaptive maths tool

Before expanding a platform, schools can run a small, time-limited evaluation. Agree on the learning objective first, record a baseline measure, and decide what evidence would count as improvement. Where feasible, compare results with a similar class or with pupils’ performance before implementation, while acknowledging that simple before-and-after comparisons cannot rule out other explanations.

  • Learning: Do pupils improve on curriculum-aligned questions, including questions they have not practised in the platform?
  • Retention: Can they still solve comparable problems after a delay?
  • Reasoning: Can they explain a method and detect an implausible answer?
  • Equity: Are gains and access similar across groups, or are some pupils receiving less useful practice?
  • Teaching: Does the system give teachers actionable information and free time for instruction, or add monitoring work?
  • Privacy and reliability: Are data use, security, accessibility and failure procedures documented?

These checks complement, rather than replace, the research literature. A 2025 open-access meta-analysis of 34 empirical studies on learning-analytics interventions reported an overall positive effect on learning outcomes, while also finding substantial variation across studies. That broader evidence concerns learning analytics interventions generally—not only AI systems or primary mathematics—so it supports careful evaluation rather than a universal claim of effectiveness. See the published meta-analysis for methods and limitations.

What the evidence does not yet tell us

Three cautions should shape decision-making. First, a small average benefit can conceal variation between pupils, schools, and implementation models. Second, data from one national context and a particular generation of adaptive software may not transfer unchanged to schools with different curricula, languages, resources, or teaching practices. Third, evidence about adaptive exercise selection should not be used to make stronger claims about generative AI tutors, which introduce different questions about accuracy, explanation quality, privacy, and student dependence.

Research on AI-supported learning more broadly similarly points to implementation as a central issue: a recent review in the Italian Economic Journal argues that the impact of computer-assisted learning and AI-guided tutors depends on curriculum alignment, teacher preparation, interactive design, and sustained human support. Read the open-access review of AI-guided tutors and computer-assisted learning for a broader synthesis.

A practical conclusion for schools

The 7,885-pupil study offers a useful reminder that adaptive learning in primary maths should be judged by the quality of learning it supports, not by the novelty of the technology. Its reported gains were small, the design was observational, and the data predate the current generative-AI wave. The most defensible response is neither blanket adoption nor blanket rejection: choose tools that fit the curriculum, use their data to inform—not automate—teacher decisions, and verify progress with independent tasks and transparent evaluation.

For a related framework on implementation planning, read our article on a five-step framework for integrating AI in education. For subject-specific design principles, see our guide to AI chatbots and higher-order thinking in STEM.

Further reading

Posted on

AI Chatbots for Higher-Order Thinking in STEM: 6 Design Principles

Teacher using a laptop in a classroom, illustrating AI teacher training and educational technology

Generative AI is often introduced into STEM lessons as a faster way to explain a concept, solve a problem, or produce an answer. A different design goal is emerging: an AI chatbot can be built to make students explain, compare, and justify their own reasoning instead of doing the thinking for them.

A study published online on 14 October 2026 in the Journal of Microbiology & Biology Education offers a timely proof of concept. Researchers developed the UCI Math ThinkBot to prompt fifth- and sixth-grade students to reflect on proportional-reasoning strategies. The study is promising, but it is not evidence that chatbots automatically improve learning. Its value lies in the instructional design choices it makes visible.

This article examines what the study found, what it cannot yet establish, and how teachers and learning designers can apply the principles responsibly.

What the October 2026 study actually tested

Richland and colleagues studied 33 students in grades five and six. After a short lesson on ways to compare ratios, students completed an assessment and then spoke with Math ThinkBot about how they had solved the problems. Rather than delivering a worked solution, the chatbot asked learners to describe their strategy, explain why it worked, compare alternative methods, and reflect on which approach was useful in different circumstances.

The researchers examined the dialogue for “higher-order thinking talk” (HOTT): language that signals comparison, relationships, inference, justification, or generalisation. Their qualitative and frequency-based analyses found HOTT cues in both the chatbot’s prompts and students’ responses. The amount of HOTT language produced by the bot and by children was positively associated.

That is a useful finding about the interaction: carefully designed dialogue can create more opportunities for students to articulate reasoning. But the study was a proof of concept with a small sample, and the chatbot conversation occurred after the lesson and assessment. The researchers did not measure whether the chatbot caused learning gains. Cue-word counts are also only a rough proxy for the quality of thinking; saying “compare” is not the same as making a sound comparison.

Primary source: Richland et al. (2026), “Developing a generative AI chatbot to support students’ higher-order thinking in STEM education,” Journal of Microbiology & Biology Education.

Why the design matters more than the chatbot label

“AI tutor” can describe very different experiences. One system may provide a complete answer after a short prompt; another may ask the learner to explain a hypothesis, inspect evidence, compare strategies, and revise an argument. Both use generative AI, but they create different demands on the learner.

Math ThinkBot was designed to avoid simply supplying the answer. Its prompts were grounded in the relevant mathematics, sample dialogues, common misconceptions, and alternative solution strategies. The researchers also constrained the chatbot to use short, student-friendly turns. These are not minor interface details: they define the pedagogical role the model is being asked to play.

The distinction connects with broader teacher-development work. A 2026 UNESCO IITE analysis of 36 national, institutional, and academic teacher AI competency frameworks stresses that AI competence should be pedagogically grounded and aligned with curriculum, implementation, and assessment—not reduced to knowing how to operate a tool. See the UNESCO IITE report on Teacher AI Competency Frameworks.

Six design principles for AI chatbots that support higher-order thinking

1. Ask for reasoning before offering an explanation

Start with prompts such as “How did you approach the problem?”, “What makes you think that?”, or “Which evidence supports your claim?” The aim is not to withhold help indefinitely. It is to make the learner’s current thinking visible before the system supplies additional information.

For example, when a student solves a ratio problem, the chatbot might ask the student to describe the relationship between the two quantities before showing another method. Teachers can then distinguish a correct answer supported by understanding from one reached by guessing or copying.

2. Make comparison a deliberate learning move

Comparison can reveal the structure of a concept. Ask students to compare two solution methods, models, scientific explanations, or interpretations. Useful prompts include “What is similar?”, “Where do the methods differ?”, “Which approach is more efficient here, and why?”, and “Would your reasoning still work if the numbers changed?”

These questions encourage learners to connect procedures with underlying relationships. They also help teachers see whether a student can transfer an idea beyond the exact example that was practised.

3. Use scaffolding without taking over

A productive chatbot should respond to the learner’s answer with a next step matched to the apparent difficulty. If a response is vague, it can request one specific reason. If the learner is stuck, it can offer a hint, a representation, or a smaller subproblem. It should not immediately replace the learner’s attempt with a polished solution.

Scaffolding needs boundaries. A model can misread a student’s intent, provide incorrect feedback, or keep asking questions that do not fit the curriculum. Teachers should be able to inspect the prompts, correct misconceptions, and intervene when the dialogue stops helping.

4. Ground the chatbot in the curriculum and likely misconceptions

General-purpose chatbots may generate plausible but irrelevant explanations. A subject-specific learning design should specify the target concept, grade level, permitted methods, common misconceptions, expected representations, and the kinds of help the system must not provide. These materials should be reviewed by a teacher or subject expert.

Grounding does not eliminate error. The chatbot should be tested against a set of realistic student responses, including incomplete reasoning, incorrect answers, ambiguous language, and attempts to get the final answer without explanation.

5. Keep each turn short and cognitively focused

Long, multi-part responses can overload learners and make it difficult to know what to do next. One focused question at a time is easier to answer and easier for a teacher to review. A useful turn should serve a clear purpose: elicit a reason, invite a comparison, test a generalisation, or help the learner reflect.

Age, reading ability, language proficiency, disability, and accessibility needs matter. Plain language, flexible response formats, and a way to request a hint can make dialogue more usable without lowering the intellectual goal.

6. End with independent transfer, not a chatbot transcript

A strong interaction should lead to a task the student completes without AI assistance. Ask the learner to solve a new problem, explain a concept to a peer, critique a new claim, or apply the same principle in a different context. This makes it possible to test whether the learner can use the idea independently.

The chatbot conversation itself is not proof of learning. Students may echo the system’s vocabulary, and a fluent explanation produced with support may not be reproducible later. Independent work is therefore essential when the educational goal is durable understanding.

A practical classroom workflow

  1. Set the learning objective. Name the concept or reasoning practice students should demonstrate, such as explaining proportional relationships or evaluating evidence for a scientific claim.
  2. Collect an initial attempt. Have students work independently first. Preserve their reasoning, not only the final answer.
  3. Run a bounded dialogue. Use a teacher-reviewed chatbot prompt that asks students to explain, compare, and reflect. Make clear that the system is a thinking partner, not an answer key.
  4. Review the interaction. Sample transcripts for conceptual errors, unhelpful loops, overconfident claims, and whether students did the reasoning themselves.
  5. Assess transfer without AI. Give students a parallel problem or short explanation task. Compare the quality of reasoning with the initial attempt using a consistent rubric.
  6. Revise before scaling. Discuss results with students and teachers, adjust the prompt or task, and repeat on a limited scale before broader adoption.

How to evaluate whether the chatbot is helping

Schools should measure learning outcomes, not merely how often students use a tool or how satisfied they report feeling. A small pilot can track several complementary indicators:

  • Reasoning quality: Does the student justify claims, connect representations, identify assumptions, or compare methods accurately?
  • Independent transfer: Can the student solve a new task without the chatbot?
  • Misconception handling: Does the system surface and address errors without reinforcing them?
  • Participation and access: Who can use the system effectively, and who encounters language, disability, device, or connectivity barriers?
  • Teacher workload: Does the design save time overall, or does reviewing transcripts and correcting errors add more work?
  • Safety and privacy: Are student data minimised, access controlled, and retention practices explained to families and staff?

Where feasible, compare the AI-supported activity with a credible alternative, such as teacher-led reflection or peer discussion. Use the same learning objective and comparable assessments. If sample sizes are small or conditions differ, report results as exploratory rather than as causal proof.

For a wider institutional checklist, see Prowad’s guides to evaluating AI learning tools with evidence and building an AI integration framework for education. They address adoption and governance; this article focuses on the interaction design that can support students’ reasoning.

Risks and open research questions

Several questions remain unresolved. The Math ThinkBot study involved 33 children, one mathematical context, and reflective dialogue after instruction. It did not establish durable learning gains, effectiveness across other STEM subjects, or superiority over teacher-led discussion. Future studies need more diverse samples, direct measures of learning, independent transfer tasks, and comparisons with alternative instructional approaches.

There is also a measurement challenge. Counting words such as “why,” “same,” or “different” can indicate that a conversation contains reasoning prompts, but it cannot fully capture whether the reasoning is correct, original, or conceptually deep. Human review or validated semantic coding is needed to judge the substance of students’ explanations.

Finally, schools should avoid assuming that more AI interaction is always better. Prowad has previously examined evidence that an AI study assistant can backfire when its design changes how students engage with learning. The relevant question is not whether AI is present, but whether the task preserves meaningful student effort and produces evidence of independent understanding.

Conclusion

AI chatbots for higher-order thinking should be designed to elicit reasoning rather than replace it. The October 2026 Math ThinkBot study offers a concrete example: ask students to explain strategies, compare alternatives, and reflect on conceptual relationships. The result is promising evidence about the potential of structured dialogue, not proof that a chatbot improves achievement.

For teachers and institutions, the most defensible next step is a bounded, curriculum-aligned pilot with teacher oversight and an independent transfer assessment. If students can explain and apply the concept after the chatbot is gone, the design may be supporting learning. If the main output is simply a fluent conversation, more evidence is needed.

References

Posted on

AI Integration in Education: A 5-Step Framework for Institutions

Teacher supporting learners during a collaborative digital learning activity

AI integration in education is no longer simply a question of whether teachers and students can access a chatbot. The harder question is whether schools and universities can turn informal experimentation into learning practices that are safe, equitable, measurable and aligned with curriculum goals.

Two studies published in Morocco in October 2026 illustrate why this distinction matters. One mixed-methods paper reports widespread informal generative-AI use among a regional sample of educators and students, alongside much less institutionally guided use. A separate qualitative study of 15 postgraduate students describes both practical benefits and concerns about confidence and intellectual independence. Neither study represents every Moroccan institution, let alone the world. Together, however, they provide timely case evidence for a broader implementation problem: access can spread faster than pedagogical guidance.

This article translates that problem into a practical five-step framework for education leaders. It combines the recent studies with international competency guidance and identifies what institutions should measure before expanding AI use.

Why AI integration in education needs an implementation plan

Schools and universities often begin with individual experiments: a teacher generates quiz questions, a student asks a chatbot to explain a difficult concept, or a department uses AI to draft learning materials. These activities may be useful, but scattered experimentation does not automatically create a coherent educational strategy.

A functioning implementation plan connects five elements: a defined learning problem, teacher and learner competence, rules for data and academic integrity, an instructional design, and evidence that the approach is helping. Without those links, institutions may measure tool adoption rather than learning.

The distinction is increasingly reflected in formal guidance. The European Commission and OECD presented an AI Literacy Framework for primary and secondary education on 18 June 2026. It describes four dimensions of engagement with AI and 19 competences, and it is intended to help educators turn AI literacy into classroom learning rather than treating it as a narrow prompt-writing skill. UNESCO’s AI competency framework for teachers similarly emphasizes human-centred practice, ethics, AI foundations, AI pedagogy and professional learning.

These frameworks are not plug-and-play implementation plans for every institution. They are reference points that schools must adapt to local curriculum, infrastructure, languages, learner needs and legal obligations.

What two recent Moroccan studies can—and cannot—tell us

In an article published on 14 October 2026, Mohsine Khrou examined generative-AI use in secondary and higher education in Morocco. The study describes a mixed-methods design involving 320 participants in the Oriental region: 80 teachers and 240 students. It reports 74% informal use, 12% guided or institutional use, and 14% non-use or rejection by caution. The article also describes concerns about AI literacy, infrastructure, critical reflection and institutional alignment. Read the original study in African Scientific Journal.

Those figures should be interpreted carefully. The sample is regional and combines distinct groups; the reported percentages are not a nationally representative estimate of AI use across Morocco. The article is useful as a local signal of a possible gap between informal uptake and structured guidance, not as proof that every school faces the same pattern.

A second paper, published in Discover Education on 17 October 2026, explored the experiences of 15 postgraduate students from two Moroccan public universities through qualitative interviews. Participants described using AI for research support, explanation, language editing and lesson preparation, while some also reported unease about depending on AI validation. Because the sample is small and purposively selected, the findings are exploratory rather than causal or nationally generalizable. The full open-access article offers a closer view of the tensions that implementation policies need to address.

The practical conclusion is not that institutions should ban AI or adopt it everywhere. It is that they should define the intended educational purpose, make expectations explicit, prepare educators and evaluate outcomes before scaling.

A five-step framework for responsible AI integration

Step 1: Start with a learning problem, not a product

Before selecting a platform, specify the problem that needs solving. Examples include helping multilingual learners rehearse academic vocabulary, giving students formative practice between lessons, reducing repetitive teacher preparation, or supporting accessible explanations of complex content.

Write a short problem statement that names the learners, the curriculum objective, the current difficulty and the desired improvement. Then ask whether AI is actually needed. A carefully designed worksheet, peer discussion, teacher conference or existing accessibility feature may be simpler, cheaper and more reliable.

For each proposed use, state what the AI may do and what remains a human responsibility. For example, AI may suggest feedback questions, but the teacher checks their accuracy and decides how they fit the learner’s needs.

Step 2: Build role-specific AI literacy

Training should go beyond demonstrations of popular tools. Teachers need to judge generated content, verify claims, protect learner information, design meaningful activities and recognize when an AI system is inappropriate. Students need to know how to question outputs, compare them with credible sources, disclose use where required and preserve their own reasoning.

Use different learning outcomes for different roles. A school leader may need to evaluate procurement and governance; a teacher may need to redesign an assessment; a student may need to distinguish a plausible answer from a supported explanation. A single introductory workshop cannot establish competence across all these tasks.

For a deeper discussion of teacher preparation, see Prowad’s analysis of AI teacher-training competency frameworks. For practical models of teacher–AI collaboration, see our guide to four teacher–AI collaboration models. For learner-facing instruction, the article on measuring AI literacy beyond prompting explores why performance and verification matter.

Step 3: Publish clear rules before high-stakes use

An institutional AI policy should answer practical questions in plain language:

  • Which uses are encouraged, restricted or prohibited in each course or activity?
  • When must students disclose AI assistance, and what evidence of their own work should they retain?
  • Which information must never be entered into public AI services?
  • Who checks accuracy, bias, accessibility and age suitability before a tool is adopted?
  • How can a learner or teacher challenge an AI-supported decision?
  • Who is accountable when the system produces an error or an unfair result?

Rules should distinguish low-risk preparation from consequential decisions. Drafting practice questions is not equivalent to using AI to grade a high-stakes assessment, determine admission, or infer a learner’s emotional state. The more consequential the use, the stronger the required human oversight, documentation and review should be.

Policies also need to respect applicable privacy, copyright, child-protection, accessibility and data-protection requirements. This article is an educational planning guide, not legal advice; institutions should have their own legal and data-protection specialists review deployments where required.

Step 4: Pilot one bounded use case and compare it with a baseline

Do not scale a tool because staff like the demonstration or because it produces polished outputs. Run a limited pilot with a defined learning objective, a realistic comparison and an agreed stopping rule.

A pilot plan should record:

  • Baseline: what learners can do before the intervention, using an assessment aligned with the objective.
  • Comparison: where feasible, compare the AI-supported approach with existing practice or another appropriate instructional design.
  • Process: how often learners use the tool, what support they receive, and how much teacher time is required.
  • Outcomes: performance on the target skill, retention after a delay, transfer to a new task and learner access across groups.
  • Safeguards: errors, privacy incidents, accessibility barriers, inappropriate outputs and complaints.

When random assignment is impractical, institutions can still collect useful evidence through pre/post measures, matched groups, structured observations and learner interviews. They should describe the limits of the design and avoid claiming that AI caused an improvement when other explanations remain plausible.

Schools evaluating a specific platform can use Prowad’s seven evidence checks for AI learning tools as a companion resource.

Step 5: Scale only after reviewing evidence, equity and workload

At the end of a pilot, convene teachers, learners, technical staff and leadership to review the evidence. Ask not only whether average performance changed, but also who benefited, who struggled, which tasks became easier, and whether the new workflow introduced hidden work or dependence on a vendor.

Scale in stages. A successful use case in one subject or age group may not transfer to another. Recheck accuracy, cost, data handling, accessibility and staff workload when the model or product changes. Maintain a non-AI alternative where appropriate, particularly when access, disability, language or connectivity could otherwise exclude learners.

For institutions serving vocational learners, implementation should be tied to authentic workplace competencies rather than novelty. Prowad’s guide to AI in vocational education and training discusses this curriculum-to-skills connection.

What should institutions measure?

A useful dashboard separates adoption from educational value. The following measures can help, but each should be selected according to the use case rather than collected simply because it is easy to count.

Dimension Possible measure Question it answers
Learning Aligned pre/post assessment; delayed retention; transfer task Did learners gain and retain the intended skill?
Quality Sampled accuracy checks; teacher review; error severity Are outputs reliable enough for this purpose?
Agency Unaided performance; learner explanation; source verification Can learners reason without simply repeating AI output?
Equity and access Participation and outcomes by relevant learner groups; accessibility testing Who is helped, excluded or disadvantaged?
Workload Teacher preparation time, review time and support requests Does the tool reduce work or shift it elsewhere?
Governance Incidents, disclosure compliance, data-handling review Are safeguards working in practice?

Institutions should set success thresholds before a pilot begins. If the goal is better formative feedback, for example, a success criterion might require improved revision quality without increased teacher correction time or a meaningful rise in factual errors. The precise threshold should be agreed locally; there is no universal percentage that guarantees an AI tool is educationally effective.

Common implementation mistakes

  • Buying before defining the need: a platform can be technically impressive yet poorly matched to curriculum or learner context.
  • Training only on prompts: learners and teachers also need verification, ethics, pedagogy and self-regulation skills.
  • Measuring clicks instead of learning: frequent use does not prove comprehension, retention or transfer.
  • Writing a policy without classroom input: rules that ignore real assignments and constraints are difficult to apply consistently.
  • Scaling from testimonials alone: satisfaction is useful evidence, but it cannot replace learning measures and review of unintended effects.
  • Assuming one pilot proves universal effectiveness: results depend on age, subject, language, task design, teacher support and access.

Conclusion: institutional readiness is a learning capability

The emerging evidence from Morocco is a useful reminder that people can begin using generative AI long before institutions have agreed on its educational purpose. The appropriate response is neither automatic adoption nor blanket rejection. It is structured experimentation with clear responsibilities, role-specific AI literacy, privacy and integrity safeguards, and evidence of learning.

For education leaders, the next step is concrete: choose one well-defined learning problem, document the current baseline, prepare the people involved, publish rules, and run a bounded pilot with a review date. Continue only when the evidence supports the educational value and the risks can be managed.

AI integration in education is successful when it improves the conditions for learning while preserving learner agency, teacher judgment and equitable access—not merely when the technology is available.

References and further reading

  1. Khrou, M. (2026, 14 October). The didactic integration of generative AI tools in secondary and higher education in Morocco. African Scientific Journal, 3(38). DOI: 10.5281/zenodo.23373372.
  2. Mellouk, F., & Ouelfatmi, M. (2026, 17 October). The impact of AI on students’ achievement, confidence, and critical thinking in education in Morocco. Discover Education, 5, 1191. DOI: 10.1007/s44217-026-02332-w.
  3. European Commission (2026, 18 June). New AI Literacy Framework helps schools prepare learners for the age of artificial intelligence.
  4. UNESCO (2024). AI competency framework for teachers.

Evidence note: The Moroccan studies provide contextual, exploratory evidence with regional or small purposive samples. Their findings should not be treated as national prevalence estimates or causal proof. The five-step framework and suggested measures in this article are implementation recommendations, not a validated intervention tested as a package.

Posted on — 2 Comments

AI Feedback Is Not the Same as Learning: What 2026 Research Shows

University instructor reviewing student work on a laptop in a classroom

Generative AI can produce detailed comments on a student’s work in seconds. But a crucial educational question remains: does receiving better feedback actually help learners improve? Recent research suggests that the answer depends not only on the quality of the feedback, but also on whether students understand, evaluate and act on it.

Why feedback quality is only part of the story

Formative feedback is information intended to help learners understand the gap between their current performance and a learning goal, then decide what to do next. Generative AI makes it possible to provide comments at scale, but fluent language should not be confused with accurate diagnosis, sound pedagogy or durable learning.

A study published in International Journal of Educational Technology in Higher Education compared teacher feedback with two forms of AI feedback in a randomized three-group design involving 70 graduate students revising argumentative essays. The researchers found that a more elaborate AI prompting approach improved the assessed quality of the feedback, but this did not produce significantly greater improvement in students’ revisions. Teacher feedback produced comparable gains in essay quality. The result highlights a distinction that matters for schools: an impressive comment is not necessarily a comment a learner can use effectively.

Read the study: “Generative AI offers more, but students revise less” (2026).

What the broader evidence suggests

A 2026 meta-analysis in Education Sciences synthesized 36 experimental and quasi-experimental studies published between 2023 and 2025, producing 72 effect sizes. It reported a moderate positive average effect of generative-AI feedback on academic achievement (Hedges’ g = 0.61). However, the analysis also found that instructional approach mattered: effects were stronger in learner-centred settings that asked students to actively construct understanding than in teacher-centred settings where learners mainly received information.

This average should not be interpreted as a guarantee that every AI feedback system improves learning. Meta-analytic results combine different learners, subjects, tools and study designs. The pooled estimate describes the included evidence, not a universal effect for every classroom or a promise of long-term retention.

Read the meta-analysis: “Can Generative AI Feedback Effectively Enhance Learning Outcomes?” (2026).

Students may judge the source, not the substance

Another open-access study in Computers and Education: Artificial Intelligence examined feedback on 979 student responses and surveyed 472 STEM students about how they judged feedback. AI-generated and human-authored feedback showed comparable pedagogical quality in the analyzed material, but both often lacked metacognitive guidance—support that helps learners plan, monitor and evaluate their own thinking. Students’ ratings were also influenced by the perceived credibility of the source.

This creates a double risk. Learners may trust AI feedback because it sounds confident, or dismiss useful feedback because they know it came from AI. Neither reaction is a reliable substitute for checking whether comments are accurate, specific, aligned with criteria and actionable.

Read the study: “Can students judge like experts?” (published in 2026).

A practical framework for educators

Schools and universities can use AI feedback more responsibly by designing a learning process around it rather than simply adding a chatbot to an assignment.

  1. Define the learning objective. Share the rubric, task requirements and expected level of performance before generating feedback. Vague goals invite generic comments.
  2. Ask for diagnosis, not just correction. Feedback should identify a specific strength, a consequential gap, evidence from the student’s work and one manageable next step. It should not silently rewrite the whole assignment.
  3. Require student verification. Learners should mark which comments they accept, question or reject, and explain why. Subject-matter claims and references must be checked rather than trusted automatically.
  4. Make revision visible. Ask students to submit an initial draft, a short response to feedback and a revised version. This reveals whether they used the advice and helps teachers identify recurring misconceptions.
  5. Include metacognitive prompts. Questions such as “What did you change?”, “What evidence supports this revision?” and “What will you try next time?” help shift attention from receiving answers to managing learning.
  6. Keep human review where it matters. Teachers should check high-stakes, sensitive or complex work and remain responsible for assessment decisions. AI output should be treated as provisional support, not an unquestionable verdict.
  7. Evaluate outcomes, not activity. Measure the quality of revisions, performance on a later independent task, retention and student understanding—not just how quickly feedback was generated or how satisfied learners felt.

Implications for assessment design

These findings support a shift from asking “Can AI generate feedback?” to asking “Under what conditions does feedback help this learner improve?” The second question requires attention to subject knowledge, task design, learner agency, accessibility and teacher workload.

For example, an instructor might use AI to generate an initial set of comments against a rubric, then sample-check them for accuracy and bias. Students could be required to respond to two comments, identify one they believe is mistaken, and demonstrate their revisions. A later, unaided task can help establish whether the learning transferred beyond the AI-supported assignment. This is a practical design proposal, not a claim that one fixed workflow has already been proven superior in every context.

Limitations and research priorities

The available studies differ in sample size, discipline, educational level, feedback design and outcome measures. The randomized essay study involved 70 graduate students, so its results should not be generalized automatically to younger learners or other subjects. The meta-analysis offers a broader synthesis, but its average effect cannot erase variation between interventions. Studies of student perceptions also do not, by themselves, establish long-term causal effects on achievement.

Future research should compare AI-supported and teacher-supported feedback over longer periods, measure independent performance after the AI is removed, and report effects across learners with different language backgrounds, disabilities and levels of prior knowledge. Researchers should also examine whether feedback systems encourage students to question explanations or merely make revisions that look more polished.

Conclusion

Generative AI can make formative feedback more available, but availability is not the same as learning. Evidence published in 2026 points to a more careful conclusion: AI feedback can be useful, yet its educational value depends on the quality of the advice, the learner’s engagement with it and the instructional conditions surrounding its use. The strongest implementation is not the one that generates the most comments. It is the one that helps students understand their errors, justify their revisions and perform better when they must think independently.

References

  • Farrokhnia, M. et al. (2026). “Generative AI offers more, but students revise less: comparing the effects of teacher and AI feedback on student essay revisions.” International Journal of Educational Technology in Higher Education. https://doi.org/10.1186/s41239-026-00579-9
  • “Can Generative AI Feedback Effectively Enhance Learning Outcomes? A Meta-Analysis of 36 Experimental and Quasi-Experimental Studies.” (2026). Education Sciences, 16(6), 816. https://doi.org/10.3390/educsci16060816
  • “Can students judge like experts? A large-scale study on the pedagogical quality of AI and human personalized formative feedback.” (2026). Computers and Education: Artificial Intelligence. https://doi.org/10.1016/j.caeai.2025.100533

Editorial note: This article synthesizes published studies and offers practical design recommendations. The recommendations are interpretations of the evidence, not direct experimental findings unless explicitly stated.

Posted on — Leave a comment

AI Accessibility in Special Education: 8 Checks Before Schools Adopt GenAI

Laptop in a classroom representing accessible digital learning and assistive technology

AI tools are increasingly presented as a route to more personalised and inclusive learning. For students with disabilities, however, a tool that can generate an explanation or simplify a text is not automatically accessible, safe, or educationally useful. A student may be able to receive an answer but still be unable to navigate the interface, formulate a prompt, interpret the response, or use it independently. Schools therefore need to evaluate not only what an AI system can produce, but whether a learner can meaningfully access, question, and benefit from it.

This question has become more urgent as new research has begun to focus specifically on inclusive AI. On 28 September 2026, UNESCO’s Institute for Information Technologies in Education highlighted a global study on AI, ICT, and inclusion for children with autism, ADHD, and learning disabilities. In a peer-reviewed study published in July 2026, special education teachers described both useful applications and barriers involving accessibility, privacy, bias, and training. A separate 2026 classroom study examined the support educators provided when students with disabilities used ChatGPT in science learning. Taken together, these sources suggest a practical principle: AI inclusion depends on the fit between the learner, the task, the interface, and the human support around the technology.

Why accessibility is more than an AI feature

In ordinary product demonstrations, accessibility may appear as a list of features: speech input, audio output, summarisation, image description, or simplified text. These can be valuable, but a feature is not the same as an accessible learning experience. A voice interface may not work reliably for a learner with a speech disability. A long AI-generated answer may overwhelm a student who needs information broken into smaller steps. A visual explanation may remain inaccessible to a learner who uses a screen reader. A chatbot may be technically usable while producing language that is difficult to interpret or that misrepresents a learner’s communication style.

The UNESCO IITE report draws on a literature review, expert interviews, and case studies from 22 countries. It proposes a system-level framework organised around six domains—People, Products, Pedagogy, Policy, Place, and Provision—and four cross-cutting conditions: Capacity, Co-creation, Consistency, and Conscience. Its central implication is that inclusion cannot be delivered by software alone. Educator preparation, learner participation, reliable provision, institutional policy, and the learning environment all influence whether technology supports meaningful participation.

This matters because the phrase “AI for special education” covers very different tools and needs. A speech-to-text tool, a generative chatbot, an adaptive practice system, an augmentative and alternative communication (AAC) aid, and an AI-powered image description service do not have the same purpose or risk profile. Evaluation should begin with a specific learner goal rather than a general assumption that AI will personalise learning.

What recent research actually tells us

A qualitative study by Marie Sakowicz and Foad Hamidi, published in Universal Access in the Information Society on 28 July 2026, interviewed seven special education teachers in public schools in the eastern United States. Teachers described using AI-enabled technologies for personalised learning and engagement, but also reported accessibility problems—especially for some students with speech and communication disabilities—as well as concerns about data privacy, algorithmic bias, and insufficient professional development. Because the sample was small and qualitative, the study does not estimate how common these experiences are across all schools. Its value is in making implementation barriers visible and identifying questions that broader research should test.

A peer-reviewed study by Kok-Sing Tang and colleagues, first published online on 12 May 2026, analysed educator support during ChatGPT use in an inclusive science classroom. The authors organised observed support into four domains: instructional, literacy, emotional-behavioural, and technological. In practice, this meant helping learners understand the purpose of an AI activity, formulate and interpret questions, remain engaged, and operate the technology—including using audio output or receiving help with typing where needed. The authors describe a situated classroom study, not a universal recipe; the taxonomy is best treated as a useful lens for planning and reflection, not proof that one approach works for every disability or age group.

These studies do not establish that generative AI improves academic outcomes for all learners with disabilities. They instead show why the quality of implementation deserves attention. UNESCO’s report likewise combines evidence and practice examples to identify opportunities and systemic barriers, rather than presenting a single controlled trial that proves the effectiveness of every tool. Schools should preserve this distinction between promising use cases, practitioner experience, and causal evidence of learning gains.

Eight checks before adopting AI for inclusive learning

1. Start with a learner-defined goal

Define the barrier the learner is trying to overcome. Is the goal to access written instructions, practise a concept, communicate an idea, plan a multi-step task, or demonstrate knowledge in a different format? Involve the student, family where appropriate, special educators, classroom teachers, and relevant support professionals. Avoid treating a diagnosis as a complete description of a learner’s preferences or abilities. Two students with the same diagnosis may need different supports, and the same student may prefer different modes for different tasks.

2. Test the complete interaction, not just the feature list

Ask the learner to complete a real classroom task using their usual access method. Can they sign in, navigate controls, enter a question, understand the response, correct an error, and save or share the result? Test keyboard-only navigation, screen readers, magnification, speech input, switch access, captions, and audio playback where relevant. The W3C’s Web Content Accessibility Guidelines (WCAG) 2.2 provide a useful baseline for digital interface accessibility, including keyboard operation, but technical conformance alone does not guarantee that a learning activity is pedagogically accessible.

3. Reduce language and cognitive friction without removing the learning goal

Check whether learners can ask questions in the mode they can use comfortably and whether responses can be adjusted for length, vocabulary, structure, and modality. A useful tool might offer one instruction at a time, a worked example, audio playback, a visual sequence, or a choice between a short and detailed explanation. But simplification should not silently remove essential concepts or lower the intellectual demand of the task. Accessibility means removing unnecessary barriers while preserving meaningful opportunities to learn.

4. Keep educators in the loop

Use AI as a supported resource, not an automatic replacement for teacher judgement or established accommodations. Model how to ask a question, check an answer, request clarification, and recognise when the system has misunderstood. The four support domains identified by Tang and colleagues offer a practical planning prompt: What instructional, literacy, emotional-behavioural, and technological support might this activity require? The answer may change during the lesson, so staff should be able to adapt support in real time.

5. Protect learner agency and provide an alternative

Students should be able to decline a tool that does not work for them and use an appropriate alternative without being penalised. Explain what the AI is doing, allow learners to correct or reject its output, and avoid making a chatbot the sole route to an essential learning resource. Where possible, include learners with disabilities in tool selection and testing before procurement. This aligns with the Universal Design for Learning (UDL) principle of designing multiple ways to engage with information and express learning, rather than expecting every learner to use the same interface.

6. Review privacy, safety, and representation

Before using a system with students, document what data it collects, who can access it, how long it is retained, whether prompts or uploads may be used to improve the service, and how records can be deleted. Do not enter identifiable student information into unapproved services. Review whether the tool produces stereotyped or demeaning descriptions of disability, misreads non-standard language, or treats a communication difference as a lack of understanding. Keep a clear route for students and staff to report harmful outputs and pause use while serious issues are investigated.

7. Measure participation and learning separately

Record more than whether the learner opened the tool or completed an activity. Useful indicators might include whether the learner could begin the task independently, how often assistance was needed, whether they could explain or apply the target concept, whether they felt in control of the interaction, and whether the accommodation reduced an existing barrier. Use a baseline or comparison with the current approach where feasible. Collect feedback from the learner and educator, and avoid treating a small pilot as proof of broad effectiveness.

8. Check who is excluded by the rollout

Consider connectivity, device availability, licensing costs, language support, compatibility with existing assistive technology, and the time required for staff training. If a school adopts a tool that only works well on recent devices or for learners who can comfortably use text-based interfaces, it may widen the very gaps it aims to close. UNESCO’s emphasis on People, Products, Pedagogy, Policy, Place, and Provision is useful here: assess the whole environment, not just the product.

A six-week, low-risk pilot for schools

The following is a proposed implementation sequence, not a validated intervention protocol. It can help a school learn whether a particular AI tool is suitable before wider adoption.

  • Week 1 — Define the goal: Select one learning barrier and one specific task. Agree on the learner’s preferred access methods and what success would look like.
  • Week 2 — Co-test accessibility: Have the learner and staff test the actual workflow, including assistive technologies, alternative input methods, and failure cases.
  • Weeks 3–4 — Run a limited pilot: Use the tool for a defined set of activities. Record support required, technical failures, learner feedback, and any safety or privacy concerns.
  • Week 5 — Evaluate independently: Check whether the learner can demonstrate the intended knowledge or skill, with appropriate accommodations but without relying on the AI to supply the answer.
  • Week 6 — Decide and document: Continue, modify, or stop the pilot based on predefined criteria. Record which learners benefited, what remained inaccessible, and what additional training or procurement conditions are needed.

Set stop conditions in advance. A privacy incident, repeated inaccessible interaction, harmful or discriminatory output, or a pattern of replacing rather than supporting the learner’s own participation should trigger review. If the pilot is small, describe its findings as local feasibility evidence. Do not present them as proof of effectiveness across disabilities, subjects, or school systems.

The strategic shift: from AI availability to inclusive capability

The emerging research points away from a narrow question—“Does this platform have AI accessibility features?”—toward a more demanding one: “Can this learner use this system to participate in this learning activity, with appropriate agency, support, and protection?” That shift makes accessibility a shared responsibility across procurement, pedagogy, professional development, governance, and product design.

For school leaders, the practical priority is not to buy the most sophisticated tool first. It is to identify the learner’s goal, co-test the real interaction, preserve alternatives, train staff, and measure meaningful participation and learning. AI may help remove barriers in some contexts; in others, it may introduce new ones. An inclusive strategy makes room for both possibilities and lets evidence—not marketing claims—guide the decision.

Sources and further reading

Evidence limitations: The cited studies include a global practice-oriented report and small qualitative research projects. They help identify design and implementation questions but do not establish that all AI tools improve learning for all students with disabilities. The six-week pilot above is a proposed local evaluation method, not a validated programme.

Posted on — 5 Comments

How to Evaluate AI Learning Tools: 7 Evidence Checks for Schools

Educators and adult learners collaborating around a laptop during a technology-supported learning session

Schools are being asked to make decisions about AI learning tools while the evidence is still developing. A platform may produce fluent explanations, adapt questions to a learner, or keep students engaged; none of those features, by itself, proves that students learn more or retain knowledge longer. The practical question for school leaders is not simply whether an AI tool works, but what it improves, for whom, compared with what, and under which conditions.

Two European Commission reviews published in September 2026 sharpen this question. One synthesises causal evidence on intelligent tutoring systems in school education; the other reviews research on generative AI among higher-education students. Separately, an October 2026 expert-consensus project from researchers at the University of Minnesota, the University of North Carolina at Chapel Hill, and the University of California, Irvine maps where generative AI may support or disrupt 65 learning processes. Together, these sources point toward a more disciplined way to evaluate AI learning tools: judge educational outcomes, not product demonstrations.

The evidence is becoming more specific—but not interchangeable

The European Commission’s systematic review of intelligent tutoring systems (ITS) in primary and secondary education concludes that these systems can contribute meaningfully to learning and skill development. The evidence for learning outcomes is more extensive and consistently positive than evidence for motivation, engagement, well-being, or socio-emotional outcomes. Findings in those latter areas are more mixed or still indicative rather than conclusive. The review also stresses that value depends on whether learner information is translated into appropriate instructional support and how the system is embedded in teaching.

That is a useful signal, but it should not be generalised to every product marketed as “AI for education.” An intelligent tutoring system with a defined subject domain, sequenced practice, and feedback is not the same intervention as an open-ended chatbot that writes essays, summarises readings, or answers any question. Different systems use different mechanisms, and they should be evaluated against different claims.

The European Commission’s separate review of generative AI in higher education, based on international literature published between January 2022 and April 2026, examines student engagement, academic performance, learning outcomes, and academic integrity while highlighting limitations in the evidence base. Meanwhile, the October 2026 expert-consensus report asked 30 learning scientists and educational researchers to assess 65 learning processes; consensus was reached on 42. The researchers suggest that generative AI may be most useful during practice and consolidation, while unreflective use during initial learning or independent application can encourage cognitive offloading. This is expert synthesis, not proof that every learner or AI system will respond in the same way.

For school decision-makers, the lesson is simple: avoid both extremes. The evidence does not justify assuming that AI automatically improves learning, nor does it justify treating all educational AI as one uniform intervention. The task is to match the tool to a learning problem and test the claim carefully.

Seven evidence checks before adopting an AI learning tool

1. Define the learning problem before evaluating the product

Start with a specific educational need: for example, learners are struggling to retrieve key vocabulary, identify errors in algebra, practise a second language, or receive timely feedback on formative exercises. “We need AI” is not a learning objective. Write down the intended change in learner performance and the group expected to benefit.

This step prevents a common procurement error: selecting a tool because its features look impressive and then searching for a problem that justifies the purchase. If the actual need is more frequent low-stakes practice, a simpler non-AI intervention may be cheaper, easier to evaluate, and just as effective.

2. Identify what kind of system is being evaluated

Describe the intervention precisely. Is it a domain-specific intelligent tutor, an adaptive practice engine, a generative chatbot, an automated feedback system, or a learning analytics dashboard? Does it give hints, reveal full answers, diagnose misconceptions, or merely generate content? Does the teacher control the sequence, or does the system make decisions autonomously?

These differences matter because evidence for one design cannot simply be transferred to another. A product should not be allowed to borrow the credibility of research on structured tutoring if its own design is a general-purpose chatbot with a different instructional model.

3. Ask for evidence on learning—not just usage

Request studies that measure outcomes aligned with the product’s claim. Useful outcomes may include accuracy on curriculum-aligned tasks, delayed retention, ability to solve unfamiliar problems, quality of explanations, or transfer to new contexts. Login counts, time spent in the platform, student satisfaction, and the speed of producing an assignment are implementation indicators; they are not substitutes for learning outcomes.

Give greater weight to well-designed comparisons with an appropriate control or alternative practice. Randomised studies can help estimate causal effects when implemented well, but a small, short trial in one subject or institution may not predict results across age groups, languages, curricula, or school systems. Observational studies and user surveys can still be informative, but they answer different questions.

4. Test unaided performance and retention

A learner may complete a task more successfully with AI assistance without being able to perform it independently afterwards. A credible pilot should therefore separate supported performance from learning that persists when the tool is removed. Include an immediate assessment without AI and, where feasible, a delayed check days or weeks later. Add a transfer task that requires learners to apply the idea to a new example.

This is particularly important for generative tools that can produce polished answers. The school should ask whether the learner has developed the underlying knowledge and reasoning—not only whether the final product looks better. Where appropriate, ask students to explain their decisions, identify an AI error, or solve a parallel problem independently.

5. Evaluate the instructional design, not just the model

Educational outcomes depend on how the technology is used. Does the tool encourage retrieval practice, give graduated hints, ask learners to explain their reasoning, and correct misconceptions? Or does it quickly reveal complete solutions? Can teachers configure it to fit the curriculum and inspect its feedback? Is AI use concentrated in a learning phase where assistance is helpful, while students still practise independent thinking and application?

The October 2026 expert-consensus report is especially relevant here: its authors distinguish acquiring information, practising to consolidate it, and applying knowledge independently. They argue that careless assistance can interfere with some of the mental work learning requires, while structured practice may offer a more promising use. Because this is consensus-based guidance rather than a trial of every product, schools should treat it as a design hypothesis to test—not a universal law.

6. Check who benefits, who may be disadvantaged, and what data are collected

Average results can hide important differences. Analyse outcomes, where sample sizes permit, by prior attainment, language background, disability or accessibility needs, and access to devices or reliable connectivity. Ask whether the system supports multilingual learners and assistive technologies, and whether its feedback is understandable and appropriate for the age group. Do not infer fairness from a vendor’s general statement that a product is inclusive.

Before a pilot, document what learner data the system collects, where they are stored, how long they are retained, whether they are used to train models, who can access them, and how deletion works. Avoid entering identifiable student information into tools that have not been approved under the school’s data-protection and safeguarding requirements. A tool that improves a narrow outcome but introduces unacceptable privacy or safety risks may not be suitable for adoption.

7. Keep teachers responsible for interpretation and decisions

AI-generated feedback, predictions, and recommendations should be treated as inputs for professional judgement, not as unquestionable decisions. Teachers need to know the system’s limits, inspect questionable outputs, correct errors, and decide when a human explanation or relationship is more appropriate. Students should also understand when AI is being used, what it can get wrong, and how to question its answers.

Schools should measure teacher workload as well as student outcomes. A tool may save time on one task but create extra work through checking, troubleshooting, or adapting generic output. The relevant comparison is the total effect on teaching and learning—not a vendor’s demonstration of how quickly a single task can be completed.

A practical pilot schools can run in eight weeks

The following is a proposed implementation model, not a protocol validated by the cited reports. It gives schools a manageable way to generate local evidence before committing to a wider rollout.

  • Weeks 1–2 — Define and baseline: Choose one subject, one learning problem, and one primary outcome. Record baseline performance and agree on privacy, safeguarding, accessibility, and teacher-oversight requirements.
  • Weeks 3–4 — Design the comparison: Specify exactly how the AI will be used and what the comparison group or existing practice will be. Train participating teachers and prepare equivalent assessment tasks.
  • Weeks 5–6 — Run the pilot: Record implementation, teacher workload, student participation, technical problems, and any unintended effects. Do not change the intervention repeatedly without documenting the changes.
  • Week 7 — Assess independently: Use an assessment completed without AI assistance. Where possible, include a delayed retention or transfer task and examine differences among learner groups.
  • Week 8 — Decide and report: Compare results with the baseline and comparison condition, document uncertainty and missing data, and decide whether to stop, redesign, extend the pilot, or scale cautiously.

Before the pilot begins, set decision rules. For example, define what level of improvement would be educationally meaningful, what workload increase is acceptable, and which safety or equity problems would halt the trial. This reduces the risk of interpreting any positive result as success after the fact. If the pilot is too small to detect reliable differences, report it as a feasibility test rather than evidence of effectiveness.

What school leaders should conclude from the latest evidence

The emerging research supports a more precise approach to AI adoption. Structured intelligent tutoring systems have a promising evidence base for some learning and skill outcomes, but results vary by outcome and context. Generative AI creates a different set of opportunities and risks, and current evidence is not strong enough to support sweeping claims about its long-term effects on learning. Expert consensus can help identify mechanisms and sensible design principles, but it does not replace controlled evaluation.

The strongest procurement question is therefore not “Which AI platform is best?” It is: “Which intervention is most likely to solve this learning problem, what credible evidence supports that claim, and how will we know whether our own students have actually learned?” Schools that ask those questions can move beyond technology adoption as a goal and treat AI as a testable part of instructional design.

Sources and further reading

Evidence note: This article synthesises recent reviews and expert consensus to propose an evaluation process. It does not claim that the proposed eight-week pilot has itself been experimentally validated, and it does not assume that findings for one type of AI system generalise to all educational tools.

Posted on — Leave a comment

AI in Vocational Education and Training: 5 Uses, Risks and a Practical Roadmap

Adult learners collaborating around a laptop in a professional training workshop

Vocational education and training (VET) must respond to changing occupational standards, digitalisation, the green transition and the growing use of artificial intelligence. Yet updating curricula and qualifications can be slow, resource-intensive work involving employers, teachers, public authorities and social partners. AI may help teams analyse evidence and prepare revisions more efficiently—but it cannot decide alone what a qualification should mean or what competent performance looks like.

The OECD’s June 2026 report, Developing Vocational Education and Training with Artificial Intelligence, examines current uses and pilots across 25 countries and case studies from ten countries. Its central message is balanced: AI can support the development of curricula, qualifications and occupational standards, but its value depends on human oversight, reliable data, quality assurance and collaborative governance.

What the OECD review tells us

The report finds that AI use in VET development remains uneven and exploratory. Public VET agencies and industry bodies appear more active than many individual providers and teachers, and most current applications support established processes rather than replace them. Examples include labour-market analysis, skills anticipation, competency mapping, synthesis of consultation responses, drafting learning outcomes and checking consistency with qualification frameworks.

This distinction matters. The report is about developing and updating VET systems—not proof that every AI tutor improves the learning of every apprentice. Curriculum development, training delivery and assessment are related but different activities. Each requires its own evidence and safeguards.

Five useful applications of AI in vocational education and training

1. Detecting emerging skill needs

Labour-market information is abundant but fragmented. AI-assisted analysis can help teams compare job vacancies, skills forecasts, occupational standards and qualification registers to identify potential changes in demand. This can help experts decide which skills deserve further investigation before a curriculum review begins.

Good practice: treat automated signals as prompts for investigation, not as a direct instruction to rewrite a programme. Vacancy data can overrepresent some employers, occupations or regions and may not reveal the full range of skills required for safe, high-quality work.

2. Mapping competencies across standards

AI can compare learning outcomes, occupational standards and qualifications to highlight overlapping, missing or inconsistently described competencies. This is especially useful where multiple frameworks describe similar skills in different language or where programmes are being modularised.

Good practice: ask subject experts to verify every proposed match. A phrase that looks similar in two documents may represent a different level of autonomy, risk or practical responsibility.

3. Drafting and revising curriculum material

Generative AI can prepare a first draft of learning outcomes, explanatory notes, assessment criteria or alternative wording. It may reduce repetitive drafting work and allow curriculum specialists to spend more time discussing priorities and validating content.

Good practice: use AI for an editable first draft, never as the final authority. Each outcome should remain observable, assessable and aligned with the actual occupational standard. Remove vague statements that sound impressive but cannot be assessed in practice.

4. Synthesising stakeholder consultation

VET development depends on input from employers, teachers, learners, regulators and other social partners. AI may help organise consultation responses, group recurring themes and prepare evidence briefs, potentially making a large volume of feedback easier to review.

Good practice: preserve minority and conflicting views rather than flattening them into a false consensus. Keep a traceable record of how stakeholder input was interpreted, and allow contributors to correct summaries that misrepresent their position.

5. Checking consistency and compliance

AI-assisted tools can flag inconsistent terminology, missing fields, duplicated outcomes or possible misalignment with a qualification framework. These checks can help quality-assurance teams identify documents that need closer review.

Good practice: distinguish mechanical checks from substantive judgement. A document can be internally consistent and still describe the wrong skills, omit an important safety procedure or fail to reflect current workplace practice.

Examples cited in the OECD report

The OECD describes several country and sector examples. England’s SkillsCompass uses natural-language processing and generative AI to analyse occupational standards, labour-market data and foresight trends. The Netherlands’ SBB-Chat supports qualification drafting and related processes. Switzerland’s ICT sector has developed occupation-specific custom GPT models for modular curriculum design and other VET tasks.

These examples show possible directions, not a ranking of products or proof that the same approach will work everywhere. The report notes that fully integrated, system-wide solutions remain rare. Countries with stronger data infrastructures and skills-intelligence systems are better positioned to move beyond small pilots.

Four risks that VET leaders should manage

  • Unreliable or biased data: incomplete labour-market records and unevenly represented occupations can lead to misleading skill forecasts.
  • Loss of human accountability: responsibility becomes unclear if institutions accept AI-generated standards or curriculum changes without named reviewers and documented approval.
  • Weaker stakeholder participation: a polished AI summary should not replace discussion among employers, teachers, learners and public authorities, especially when interests conflict.
  • Privacy and security exposure: unpublished qualification material, employer data and sensitive consultation responses may require restricted access, retention limits and approved tools.

These are governance problems as much as technical ones. Providers also need staff with sufficient AI, digital and data literacy, secure tools suited to the task, and guidance that reflects the realities of vocational education. Smaller institutions may face particular constraints in expertise, infrastructure and funding.

A practical 90-day roadmap for responsible adoption

The following roadmap is a proposed implementation approach informed by the OECD’s findings; it is not a timetable prescribed by the report.

Days 1–30: Choose one bounded problem

Select a specific task, such as comparing a set of occupational standards or synthesising consultation feedback. Establish a baseline: how long does the current process take, what errors recur, and who must approve the result? Map the data involved and identify privacy, security and legal requirements before staff upload any documents.

Days 31–60: Run a supervised pilot

Use an approved tool with a small team of curriculum specialists and subject experts. Require reviewers to check factual claims, source coverage, missing perspectives and alignment with the relevant standard. Record corrections and the time spent reviewing AI output as well as the time saved during drafting.

Days 61–90: Evaluate and decide

Compare the pilot with the baseline. Possible measures include review time, factual error rate, missing competency flags, consistency across documents, stakeholder satisfaction and the proportion of AI suggestions accepted after expert review. Do not use speed alone as the success criterion. If the tool saves time but introduces errors that are difficult to detect, the apparent gain may be illusory.

At the end of the pilot, document what the tool may be used for, what it must never decide independently, who signs off on outputs, how errors are reported and when the experiment should stop. Scale only when the evidence supports it and the institution can maintain the safeguards.

How to connect curriculum reform with training outcomes

Updating a curriculum is only one part of the system. Institutions also need to know whether training helps learners acquire and retain the intended competencies. That requires separate evaluation of teaching, practice, assessment and transfer to real tasks. Our related article on AI training at work and a 2,574-employee field experiment discusses why learning outcomes and later application should be measured rather than assuming that a technology feature guarantees success.

Providers evaluating digital tools can also use Prowad’s evidence checklist for AI learning tools as a starting point, adapting it to occupational standards, practical assessment and workplace risk.

Conclusion

AI offers VET systems useful support for labour-market analysis, competency mapping, drafting, consultation and quality checks. The OECD’s 2026 review shows that these applications are emerging across countries, but adoption remains uneven and integrated solutions are still uncommon. The responsible approach is not to automate curriculum decisions wholesale. It is to use AI for bounded analytical and drafting tasks, keep expert judgement and stakeholder participation central, protect sensitive data, and evaluate whether the resulting qualifications remain accurate, relevant and trusted.

Reference

OECD (2026). Developing Vocational Education and Training with Artificial Intelligence. OECD Reviews of Vocational Education and Training. OECD Publishing, Paris. Published 23 June 2026.

Posted on — 3 Comments

AI Teacher Training in 2026: What 36 Competency Frameworks Reveal About Preparing Educators

Teacher using a laptop in a classroom, illustrating AI teacher training and educational technology

Artificial intelligence is entering classrooms faster than many education systems can redesign teacher preparation. The central question is no longer whether educators should encounter generative AI, but what they need to understand, evaluate and do with it—and how institutions can tell whether training has changed professional practice.

A useful starting point is the 2026 UNESCO IITE analytical report Teacher AI Competency Frameworks. The report systematically examines 36 national, institutional and academic frameworks. Read alongside the OECD’s 2026 work on AI literacy, it points toward a shift from tool familiarity to pedagogically grounded competence.

Why AI teacher training needs a stronger foundation

Many introductory courses focus on prompts, lesson-plan generation, quiz creation or presentation design. These are useful entry points, but they do not by themselves demonstrate that a teacher can judge the reliability of an AI-generated explanation, protect student information, redesign assessment or decide when AI should not be used.

This distinction matters because successful task completion is not the same as successful learning. The OECD Digital Education Outlook 2026 reviews emerging evidence that generative AI can support learning when guided by clear teaching principles, while unguided outsourcing may improve the immediate product without producing equivalent learning gains.

For teacher development, the implication is practical: a course should not be judged only by whether participants can operate an AI tool. It should also assess whether they can align its use with learning objectives, verify its outputs, preserve learner agency and explain their pedagogical decisions.

What the 2026 review of 36 frameworks contributes

UNESCO IITE’s analytical report compares 36 frameworks and examines how they define teacher AI competence, how implementation is organized, and how competence is evaluated. It highlights the importance of curriculum alignment, pedagogical grounding and coherent approaches to teacher development rather than treating AI adoption as a stand-alone technical exercise.

The report is a mapping of frameworks, not a randomized trial proving that one training model produces better classroom outcomes than another. Its value is different: it helps decision-makers compare the concepts, implementation scenarios and evaluation methods being used to prepare educators for AI-enabled teaching.

Five connected dimensions of effective AI teacher training

1. Understand AI and its limitations

Teachers need an accessible understanding of how generative AI produces outputs, why confident answers can be wrong, how bias can appear, and why model responses may vary. Training should include practical verification: checking claims against primary sources, distinguishing evidence from speculation and identifying missing context.

2. Connect AI use to pedagogy and curriculum

AI should be selected because it serves a defined learning purpose—not because it is new. Educators can compare a conventional activity with an AI-supported version, identify which thinking remains the learner’s responsibility, and check alignment with curriculum outcomes. This is especially important when generating differentiated examples, formative feedback or lesson materials.

3. Design assessment that makes thinking visible

When students can obtain fluent answers quickly, assessment design needs to reveal reasoning, not merely the final text. Useful approaches include oral explanation, staged drafts, source evaluation, reflective notes, in-class problem solving and tasks that require learners to critique an AI response. No single method is a universal solution; choices should fit the subject, age group and learning objective.

4. Protect privacy, fairness and academic integrity

Professional competence includes knowing which student data must not be entered into an external system, checking institutional rules, considering accessibility and language bias, disclosing AI use where required, and keeping meaningful human oversight. AI detection scores should not be treated as conclusive proof of misconduct without additional evidence and a fair process.

5. Develop professional judgment through practice

Teachers need opportunities to test a tool against authentic classroom problems, review errors, discuss cases with colleagues and revise their practice. A one-off awareness session can introduce concepts, but sustained, practice-oriented professional development is better suited to building habits that can transfer to real teaching contexts. A 2026 systematic review of in-service teacher AI literacy likewise identifies competence, self-efficacy, attitudes and institutional conditions as connected parts of the field.

How can institutions evaluate AI literacy among teachers?

A credible evaluation plan combines more than a satisfaction survey or self-reported confidence score. Institutions can ask participants to complete authentic tasks and score their work with a transparent rubric. For example, a teacher might be asked to generate a lesson activity, verify two factual claims, identify a privacy risk, adapt the activity for learners with different needs, and justify whether AI improves the intended learning outcome.

A practical rubric can assess four levels: basic awareness; guided use; independent evaluation and adaptation; and reflective, responsible integration into teaching. These levels are a proposed operational model for professional development, not a claim that UNESCO mandates this exact four-level scale.

  • Knowledge: Can the teacher explain core capabilities, limitations and risks?
  • Verification: Can the teacher check outputs against reliable evidence?
  • Pedagogical design: Can the teacher justify the tool’s role in relation to a learning objective?
  • Responsible practice: Can the teacher identify privacy, fairness and integrity concerns?
  • Reflection: Can the teacher explain what changed after reviewing evidence from classroom use?

A 30-day model for AI professional development

Institutions looking for a manageable starting point can organize a month-long pilot. The schedule below is a proposed design for testing and adaptation, not a universally validated intervention.

  1. Week 1 — Foundations: Introduce AI literacy, common failure modes, verification and privacy. Use short scenarios rather than tool demonstrations alone.
  2. Week 2 — Lesson design: Participants redesign one lesson or training activity, specifying the learning objective and the role—if any—of AI.
  3. Week 3 — Assessment and feedback: Review how AI changes the evidence of learning. Create a task that makes student reasoning visible and test it with colleagues.
  4. Week 4 — Evaluation and reflection: Score practical work using a rubric, document unresolved risks and agree on a small next step for classroom practice.

Before scaling the programme, institutions should collect baseline and follow-up evidence, review participant work, listen to learners and teachers, and check whether the approach is feasible across subjects and resource settings. A pilot can reveal implementation problems; it cannot, by itself, establish long-term causal effects.

What this means for schools, universities and training providers

Schools need clear guidance on approved tools, student data and assessment expectations. Universities need to connect AI policy with disciplinary teaching, academic integrity and staff development. Vocational and professional training providers can focus on authentic workplace tasks while teaching learners to validate AI outputs and recognize when human expertise remains essential.

The OECD’s 2026 AI literacy framework for primary and secondary education reinforces the wider need to help learners understand AI systems, evaluate their outputs and use them ethically and creatively. Teacher development and student AI literacy should therefore be designed as connected parts of an educational strategy, not separate technology projects.

Conclusion: measure judgment, not just tool use

The emerging direction in AI teacher training is clear: moving beyond prompt-writing workshops toward a combination of technical understanding, pedagogical design, critical evaluation, ethical practice and reflective professional learning. UNESCO’s mapping of 36 frameworks offers a useful evidence-informed reference point, while the OECD’s 2026 work stresses that educational value depends on how AI is used.

The strongest programme is not necessarily the one that introduces the greatest number of tools. It is the one that helps educators make better decisions about when to use AI, how to check it, what learners should still do themselves, and how to recognize whether learning has actually improved.

References and further reading

Editorial note: This article synthesizes policy frameworks and research literature. The 30-day programme and evaluation rubric are practical proposals for local testing, not claims of experimentally established effectiveness.

Posted on — Leave a comment

When an AI Study Assistant Backfires: Evidence from a 2,379-Student University Trial

University student studying at a desk near large library windows, illustrating research on AI study assistants and student engagement.

Research · Education · Practice

Generative AI tools are increasingly being integrated into university learning platforms on the assumption that on-demand explanations and answers will make study more efficient. A randomized university trial at the University of Maryland complicates that assumption. In the Fall 2025 semester, researchers evaluated access to a course-integrated virtual study assistant across multiple disciplines. The working paper reports lower final grades and reduced engagement with the university learning-management system among students offered access in the principal within-course comparison.

The findings are important, but they require careful interpretation. The study evaluated one institutional tool, under particular conditions of implementation and uptake. It does not establish that AI tutoring in general harms learning, nor does it identify a single mechanism that explains the observed differences.

The study and its design

Liu and colleagues examined the University of Maryland’s Virtual Study Assistant (VSA), a generative-AI tool embedded in the university’s learning-management system. It was built on GPT-4o and used retrieval-augmented generation to draw primarily on course materials selected by instructors. During Fall 2025, the study involved 2,379 undergraduate students and 30 instructors across multiple disciplines.

The researchers used a randomized controlled design to evaluate access to the tool. The working paper reports a particularly informative comparison between sections of the same course: students offered access to the VSA had final grades lower by 0.37 standard deviations, while recorded participation in the learning-management system was lower by 0.90 standard deviations. The authors also report that estimated academic losses were larger for first-generation students. These are standardized effect sizes, not percentage-point changes; the university’s summary describes the grade difference in the matched-course comparison as approximately four percentage points.

Source: Liu, J., Sweet, T., Chen, M. H., Engelberg, J., Clark, M., Persaud, A., Lancaster, A., Hollingsworth, J., Rice, J. K., & Masters, M. (2026). The Effects of Course-Integrated AI Tutoring on Student Performance and Engagement: A Randomized University Trial. EdWorkingPaper No. 26-1598, Annenberg Institute at Brown University. https://doi.org/10.26300/y3f8-vh05. This is a working paper and should not be described as a peer-reviewed journal article.

Access is not the same as use

One of the study’s most consequential details is the low uptake: only about 15% of students offered the VSA used it at least once. The reported estimates therefore primarily concern the consequences of being offered access in this institutional setting—not the effect of intensive use by a typical student, and not a clean comparison between frequent AI users and non-users.

Among students who did use the assistant, reported query patterns also raise questions about how the tool functioned in practice. Approximately 73.8% of requests sought information, explanations, or solutions; 11.3% concerned practice or test preparation; and 0.7% sought feedback on the student’s own work. The tool had a default mode that could provide direct answers, while a tutoring mode was designed to guide students toward a response. Few instructors switched away from the default setting.

These observations are consistent with a possible mismatch between the intended role of an AI “tutor” and the role students actually assigned it: quick information retrieval or answer delivery rather than sustained practice. However, usage patterns alone do not prove that answer-seeking caused lower grades. They are descriptive evidence that helps frame hypotheses for subsequent research.

What might explain the results?

Several mechanisms are plausible, and the available evidence does not establish which one is decisive.

  • Displacement of course engagement. Students may have relied on the assistant instead of opening readings, revisiting lecture materials, or completing other activities in the learning platform. The observed decline in recorded platform participation is consistent with this possibility, but LMS activity is an imperfect proxy for learning: fewer clicks do not necessarily mean less understanding.
  • Answer substitution rather than guided practice. When a system supplies a solution before a learner has attempted the task, it may reduce opportunities for retrieval, explanation, error correction, and productive struggle. The request patterns make this hypothesis credible, but the trial was not designed to isolate the cognitive mechanism.
  • Implementation and trust. The tool was integrated into a course platform where instructors could access chat logs. Awareness of that context, alongside access to other tools such as ChatGPT and Gemini, may have influenced who used the VSA and what they were willing to ask. This limits comparisons between the institutional assistant and private, standalone AI tools.
  • Instructional configuration. A tool’s effects may depend on whether it provides direct answers, prompts students to explain their reasoning, connects responses to assigned readings, or is integrated into assessment and classroom routines. The results should not be treated as a test of every possible tutoring design.

Important limitations and unresolved questions

First, the paper is a working paper, not yet a peer-reviewed publication. Its estimates should be treated as provisional and revisited if the authors release revised analyses or a journal version.

Second, the intervention was access to a specific course-integrated assistant at one large U.S. public university. Its findings cannot automatically be generalized to other age groups, countries, subjects, models, or AI systems designed around structured tutoring. The results also do not show that AI use outside the VSA produced the same effects.

Third, low uptake matters for interpretation. An estimate of the effect of being offered access answers a practical policy question—what happened when this university made the tool available under these conditions?—but it does not tell us what would happen if students were trained to use a different tool intensively and appropriately.

Fourth, reduced learning-management-system activity is a behavioral measure, not a direct measure of conceptual understanding, retention, transfer, or long-term learning. Lower activity may signal displacement of course work, but alternative explanations should be tested. The larger estimated losses among first-generation students also warrant careful follow-up; they should not be interpreted as proof that AI tools inherently widen educational inequality.

Finally, randomized field trials estimate the effect of an intervention package in a real setting. They do not necessarily identify the causal pathway behind an outcome. Access, faculty choices, tool configuration, students’ existing AI use, and the surrounding course environment may interact. The trial is therefore a reason to investigate deployment conditions, not a universal verdict on AI tutoring.

Implications for educators and institutions

The most defensible practical conclusion is that access to an AI tool should not be assumed to constitute an effective learning intervention. Institutions should define the learning purpose before adoption, explain how student data and conversations are handled, and evaluate the effects on actual learning rather than satisfaction or convenience alone.

  • Prefer scaffolding over immediate completion. Where appropriate, configure assistants to offer hints, ask learners to show an initial attempt, diagnose errors, and reveal worked solutions in stages.
  • Reconnect AI use to primary materials. Ask students to identify the relevant reading, lecture segment, evidence, or worked example after using the assistant.
  • Make learning visible. Use low-stakes retrieval practice, short explanations in students’ own words, in-class application, and assessments that test transfer—not just the answer produced during an AI-supported task.
  • Monitor outcomes and equity. Compare engagement, performance, and student experience across groups, while avoiding surveillance practices that are disproportionate or poorly explained. Be prepared to revise or pause a deployment when it displaces useful learning activity without demonstrable benefit.
  • Evaluate alternatives experimentally. Future studies should compare direct-answer systems with guided tutoring, measure learning after AI support is removed, track longer-term retention and transfer, and report implementation fidelity and subgroup uncertainty.

These are design recommendations derived from the study’s findings and wider learning-science principles; they were not all directly tested in this trial. Their effectiveness should itself be evaluated rather than assumed.

How this fits the wider evidence

The Maryland result should be read alongside, not instead of, other research. Bastani and colleagues’ randomized study in a high-school mathematics setting found that access to a general-purpose GPT interface could improve performance while it was available, yet some gains did not carry over to an unaided assessment; a more constrained tutor designed with learning safeguards produced a different pattern. That study is not a direct replication of the Maryland trial: the learners, subject, intervention, and outcomes differ. It nevertheless supports a useful research question—whether an AI system helps students learn independently, rather than merely complete the immediate task.

Reference: Bastani, H., et al. (2025). “Generative AI Can Harm Learning.” Proceedings of the National Academy of Sciences. https://doi.org/10.1073/pnas.2422633122.

For the broader institutional context, see the OECD’s Digital Education Outlook 2026, which discusses the need to evaluate generative AI in relation to educational goals, teacher agency, and learning processes rather than tool availability alone: https://doi.org/10.1787/062a7394-en.

Conclusion

The Maryland trial provides a cautionary empirical result: in one large university implementation, offering access to a course-integrated AI study assistant coincided with lower final grades and substantially lower recorded engagement with course materials. The result is important precisely because it resists a simple technological narrative. Yet the paper does not establish that AI tutors as a class are harmful. It shows that design, uptake, instructional context, and the learning activities a tool may displace need to be measured—not assumed.

For universities, the relevant question is not simply whether students can access AI, but under what conditions its use supports durable understanding, independent performance, and equitable learning outcomes.


Related reading on Prowad: AI Tutors for Students: What the New Study Agents Mean for Learning; AI and Independent Learning: What a 1,222-Person Study Found; Does AI Really Hurt Critical Thinking?.

Image credit: Austin / Unsplash.

Posted on — 1 Comment

AI and Independent Learning: What a 1,222-Person Study Found

University student studying independently in a library, illustrating the relationship between AI assistance and learning without support.

Research · Education · Practice

An AI assistant can help someone solve a problem correctly in seconds. But does that mean the person has learned how to solve it? A set of three randomized experiments involving 1,222 US-based adults suggests that the answer depends on what the AI does for the learner—and what happens when the help disappears.

The paper, “AI Assistance Reduces Persistence and Hurts Independent Performance” by Grace Liu, Brian Christian, Tsvetomira Dumbalska, Michiel A. Bakker and Rachit Dubey, was first submitted to arXiv on 6 April 2026 and last revised on 3 October 2026. It is a research preprint, so its findings should be treated as important but not yet as a settled verdict about AI-assisted education.

The central distinction: performance is not the same as learning

When a learner uses AI, the immediate task score can improve because the system supplies an explanation, a hint or even the answer. That score alone cannot tell us whether the learner has built knowledge they can retrieve independently later. To test this distinction, the researchers measured performance both while AI was available and after it was removed.

The paper reports three randomized experiments: two using fraction problems and one using reading-comprehension questions. In total, 1,222 people were recruited through the online research platform Prolific. Participants were adults in the United States—not a sample of schoolchildren—and each task session lasted roughly 10–15 minutes.

What the experiments found

In the first experiment, participants worked on fraction problems with or without an AI assistant. The AI condition used GPT-5 in a sidebar, with the system pre-prompted with each problem and its solution so that participants could request direct answers. After the practice phase, the assistant was removed and participants attempted three further problems independently.

  • While AI was available: participants with AI solved more problems correctly and skipped fewer questions.
  • After AI was removed: the analysed AI group solved a lower share of the final fraction problems than the control group—57% versus 73%. The difference was statistically significant, with a reported Cohen’s d of −0.42.
  • Persistence also mattered: in that first experiment, the AI group skipped more of the final questions—20% versus 11%. This difference was statistically significant, though the effect was smaller than the performance difference.

The researchers then repeated the fraction experiment with methodological changes intended to address a potential confound in the first experiment. The independent solve rate was again lower in the AI condition: 71% versus 77%, a smaller but statistically significant difference (Cohen’s d = −0.19). The overall difference in skipping questions was not statistically significant in this second experiment.

A third experiment tested reading comprehension. After the AI assistant was removed, the analysed AI group answered fewer of the final questions correctly than the control group—76% versus 89%—and skipped more questions. Both differences were statistically significant in this experiment.

These are not proof that AI permanently damages skills. They are evidence that, in these short experimental tasks, access to a system that readily supplies answers was followed by weaker performance on a small set of unaided questions.

Why the type of AI help may matter

One of the paper’s most educationally relevant analyses examined how participants used the assistant. In the second fraction experiment, 61% of AI-condition participants said they mainly used it to obtain direct answers, 27% said they mainly sought hints or clarifications, and 12% reported not using it. The authors found that poorer independent performance and some of the persistence differences were concentrated among those who sought direct solutions.

This comparison needs careful interpretation: participants were not randomly assigned to “answer-seeking” or “hint-seeking” styles, so this part of the analysis cannot establish that one prompt style caused the difference. People who chose different styles may also have differed in other ways. Nevertheless, it offers a useful hypothesis for educators to test: AI that completes the cognitive work may have different consequences from AI that prompts learners to do the work themselves.

How strong is the evidence—and what are its limits?

The study has several strengths. It uses randomized comparisons, includes a replication of the fraction task with improved controls, and tests a second domain—reading comprehension. The findings therefore go beyond a survey asking people whether they feel more or less capable after using AI.

But the boundaries of the evidence are just as important:

  • Short exposure and short follow-up: the experiments measured performance immediately after brief AI-assisted sessions. They do not establish whether any difference persists over weeks or months.
  • Adult online participants: the findings cannot be transferred directly to children, teenagers, classroom teaching or every educational subject.
  • A specific form of assistance: the AI was configured to make direct answers readily available. This is not a test of every AI tutor, guided practice system or classroom implementation.
  • Small final test sets: the unaided outcome was measured using only a few questions after the assistance phase, so the size and generality of the effect require further study.
  • Not every result was consistent: the overall persistence difference was not statistically significant in the second fraction experiment, even though the performance difference was.

The right conclusion is therefore narrower than “AI makes students less intelligent.” The study suggests a risk: when a learner repeatedly receives solutions instead of practising the reasoning, immediate success may not translate into independent performance once the support is gone. A language-learning example is explored in our guide to AI vocabulary learning and independent word use.

How this fits with the wider research

The result is consistent with a more directly educational field experiment published in Proceedings of the National Academy of Sciences in 2025. In a study involving nearly 1,000 high-school mathematics students, Bastani and colleagues compared an unrestricted GPT-4 interface with a tutor designed with learning safeguards. Access to AI improved performance during practice, but students using the unrestricted version performed worse on a subsequent unaided test than students who had not received that assistance. The scaffolded tutor produced a different pattern, underscoring that the design of the help matters. Read the PNAS study.

The OECD’s Digital Education Outlook 2026 makes a related point: general-purpose generative AI can improve task performance without necessarily producing learning gains when it is used without pedagogical guidance. Taken together, these sources do not show that AI is inherently harmful. They point to a more practical question: is the tool designed to finish the task, or to help the learner become able to do it?

For a broader overview of cognitive offloading and critical thinking, see Prowad’s earlier analysis of AI and critical thinking. For classroom routines that protect retrieval and independent recall, see Prowad’s guide to AI and student memory. For the product-design side of this question, read our analysis of AI tutors and study agents. This article focuses more narrowly on the evidence from randomized tests of what happens after assistance is removed.

What educators can do now

The evidence supports cautious design principles rather than a blanket ban on AI. Teachers and learning designers can test the following approaches:

  1. Ask for an attempt before revealing the answer. Have learners write down a first step, prediction or explanation before asking AI for help.
  2. Prefer graduated hints to complete solutions. Start with a question or small clue, and reveal more only when the learner is genuinely stuck.
  3. Fade the assistance. After a worked example, give learners a similar problem to solve without AI. This checks whether they can transfer the method independently.
  4. Make reasoning visible. Ask learners to explain why a step works, identify a possible error, or compare two solution paths—not simply submit the final answer.
  5. Assess learning without the tool as well as with it. Use short retrieval questions, oral explanations, or a brief unaided task alongside AI-assisted work. The goal is to measure both supported performance and independent competence.
  6. Evaluate the intervention, not just satisfaction. If a school introduces an AI tutor, compare learning outcomes and retention against an appropriate alternative, rather than relying only on usage, speed or student enthusiasm.

These are design implications informed by the evidence, not interventions all directly tested by the 1,222-person study. Their effectiveness should be evaluated in the relevant classroom, subject and age group.

The takeaway: design AI around the learner’s next independent step

The most useful question is not whether AI can produce a correct answer. It is whether the interaction leaves the learner better prepared to reason when the answer is no longer available. The new experiments provide a warning about immediate-answer assistance, while the wider evidence suggests that guided, pedagogically purposeful use may lead to different outcomes.

For schools and universities, this means judging educational AI not only by what students accomplish with it, but also by what they can explain, remember and do independently afterwards.

Sources and further reading

  • Liu, G., Christian, B., Dumbalska, T., Bakker, M. A., & Dubey, R. (2026). AI Assistance Reduces Persistence and Hurts Independent Performance. arXiv preprint, submitted 6 April 2026; version 5 revised 3 October 2026. https://arxiv.org/abs/2604.04721
  • Bastani, H., et al. (2025). Generative AI without guardrails can harm learning: Evidence from high school mathematics. Proceedings of the National Academy of Sciences, 122(26), e2422633122. https://doi.org/10.1073/pnas.2422633122
  • OECD (2026). OECD Digital Education Outlook 2026: Exploring Effective Uses of Generative AI in Education. https://doi.org/10.1787/062a7394-en

Editorial note: The lead study is an arXiv preprint. Its latest version is dated 3 October 2026; the article does not treat it as a newly published journal paper or as definitive evidence of long-term effects.