Posted on — Leave a comment

Can an AI Discussion Partner Help Students Speak Up in Class? Evidence from 759 MBA Students

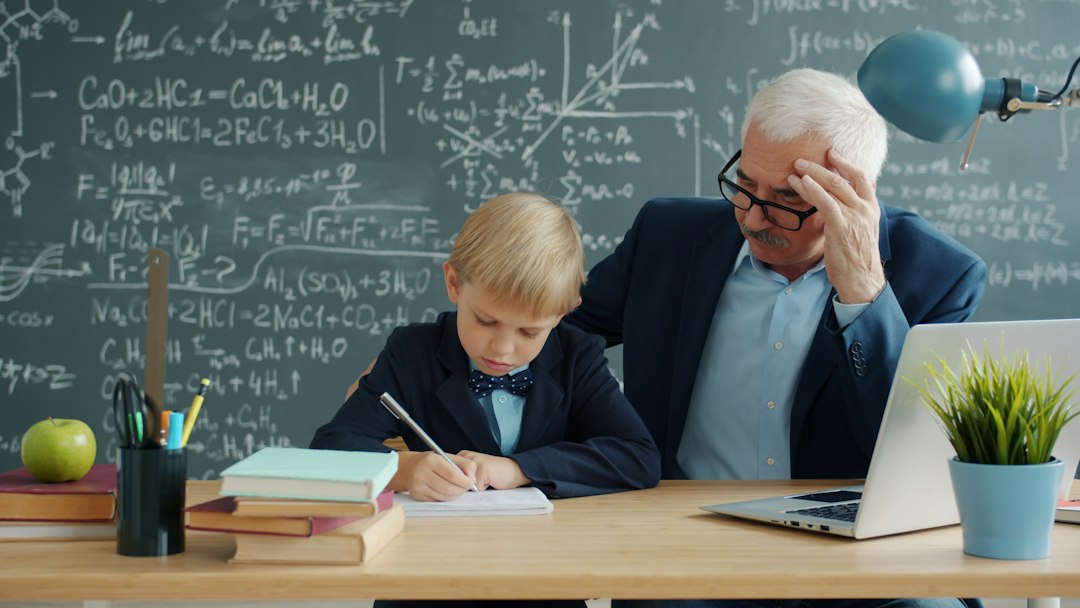
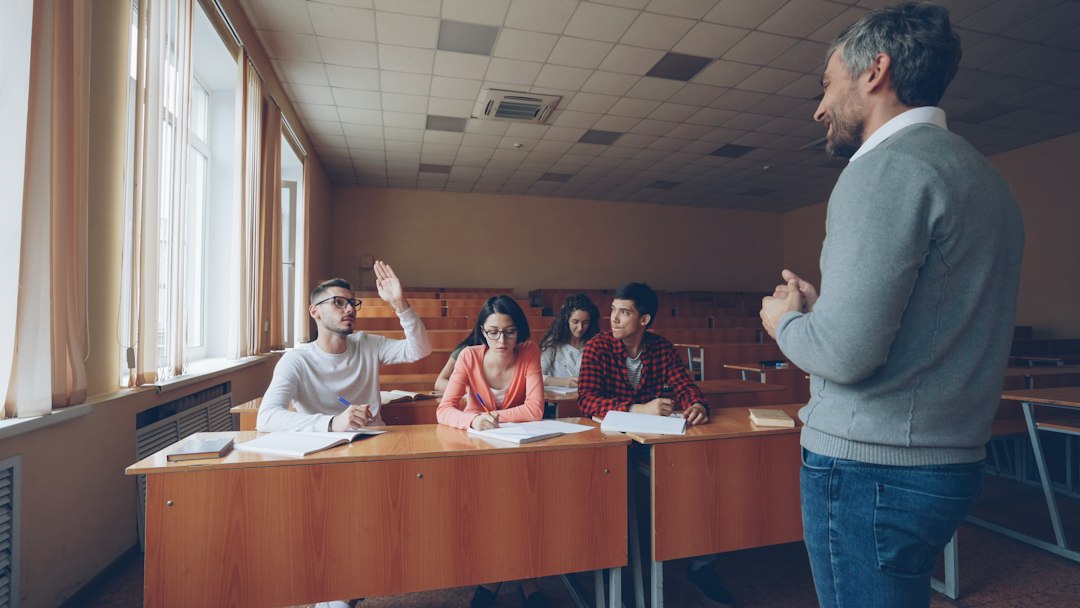
A student raises his hand to contribute during a classroom discussion while the teacher listens.

Some students understand a case, have a view, and still say very little when the class discussion begins. The obstacle may not be a lack of ideas alone. It can also be the pressure of turning an unfinished thought into a public contribution while classmates and an instructor are listening.

A newly posted working paper from Columbia Business School offers an intriguing test of whether practice with a voice-based AI discussion partner can help. In a preregistered field experiment involving 759 MBA students across ten course sections, students were assigned to rehearse with a purpose-built AI partner before two class discussions. After a second assigned use, the researchers observed more voluntary contributions in later sessions. The estimated increase was about 31% relative to the sample’s average contribution rate.

The result is promising, but it needs careful interpretation. The paper is an October 2026 arXiv preprint and has not yet been peer reviewed. It studied one professional-degree course at one US business school, and the intervention used a specialised debate partner—not an ordinary chatbot. The finding is best treated as evidence for a design worth testing, not a guarantee that any AI conversation will make students more confident or improve achievement.

What the 759-student field experiment tested

Dan J. Wang and colleagues conducted the study in a required first-year MBA strategy course during Fall 2025. Ten course sections used a case-discussion format. Each of the 759 students was randomly assigned two of ten eligible case sessions for which they could prepare with a voice-based AI tool called CAiSEY. The timing of the two assignments varied across students, allowing the researchers to compare participation before and after students had received different amounts of practice.

CAiSEY was designed around the case students had to read before class. The student selected a position on a discussion question. The AI automatically took the opposing position, and the student defended their view in a spoken exchange. The system challenged arguments and introduced alternative perspectives. After the conversation, the student submitted a written reflection and received an automatically generated summary and feedback.

This was not simply a chatbot asked to summarise a case. Its instructional role was closer to a debate partner: it required the learner to state a position, respond to a challenge, and prepare to explain the reasoning aloud. Instructors and teaching assistants were blind to students’ assignment timing. Teaching assistants recorded contributions during class and distinguished voluntary comments from answers prompted by a cold call.

The researchers analysed several thousand student-session observations. The participation models that separated students’ first and second assigned opportunities included 504 students and 4,787 student-sessions. The study also used midterm and end-of-term surveys to examine students’ reported comfort, focus, motivation, and perceived learning.

Read the working paper: How assigned AI use before class shapes active student engagement in class (arXiv, submitted 7 October 2026).

What changed—and when

The most important detail is that the effect was delayed and depended on repeated practice. The researchers found no detectable increase in participation during the very class session for which students first prepared with CAiSEY. A first assigned opportunity on its own did not produce a lasting increase in later voluntary contributions.

After the second assigned opportunity, however, students contributed more in the next class and across subsequent sessions. For students whose conversations met the study’s qualifying-use definition, the estimated additional effect corresponded to roughly one extra voluntary contribution every four to five sessions—about 31% of the sample’s average contribution rate. The paper also reports that the positive pattern remained when the qualifying conversation threshold was shortened to four minutes.

Students who used the tool more also reported greater comfort speaking up and greater perceived learning by the end of the course. The researchers did not find corresponding evidence that use increased students’ reported mental focus or motivation. These are different outcomes, and the distinction matters: a student can become more willing to contribute without necessarily feeling more focused or motivated overall.

The 31% figure should not be read as a universal promise or as a 31% improvement in test scores. It describes an estimated change in voluntary classroom contributions after repeated use in this particular course. Participation is a meaningful learning behaviour, but it is not the same as long-term retention, conceptual mastery, or the quality of every contribution.

Why might a voice AI discussion partner help?

The authors propose two related mechanisms. First, rehearsing a case may help students organise what they know. A student who has already stated a position, heard a counterargument, and tried to defend the position may arrive with a clearer starting point. Second, low-stakes practice may reduce the fear of being judged for an imperfect answer. A learner can try an argument, pause, revise it, and respond again without making the first attempt in front of the whole class.

These explanations are plausible, but they should not be confused with proven mediators. The field experiment measured participation and students’ reported experiences; it did not establish that reduced anxiety or improved subject mastery alone caused the behavioural change.

Related peer-reviewed research points in a similar direction while also highlighting the limits of AI-mediated interaction. A 2026 study in Neuron compared brief pre-lecture conversations with a human instructor, an AI instructor, or no instructor interaction among 57 university students. Both human- and AI-led interactions were associated with better performance on difficult comprehension questions than no interaction, and the two instructor conditions did not differ significantly on the measured learning scores. However, students reported less social closeness with the AI instructor and showed lower gaze alignment than with the human instructor. The laboratory study is small, but it reinforces an important distinction: AI can provide some forms of preparation and scaffolding without reproducing the social relationship created by a person.

Read the peer-reviewed Neuron study: Scaffolding human and AI instruction—Neural alignment and learning gains in online education.

A six-step pre-class routine teachers can adapt

Teachers do not need to copy CAiSEY or assume that a general-purpose voice chatbot will reproduce the study’s result. They can test the underlying instructional sequence on a small scale, using an institutionally approved tool and a clear alternative for students who cannot or do not wish to use voice AI.

  1. Ask students to read and think first. Before opening an AI tool, each student reads the assigned material and writes a provisional position, one supporting piece of evidence, and one point they do not yet understand. This protects the learner’s own first attempt.
  2. Give the AI a bounded opposing role. The student states their position and asks the AI to challenge it with a plausible counterargument based on the supplied case or course material. The AI should not be asked to decide who is right.
  3. Require spoken defence, not passive listening. The student responds aloud, explains the evidence, and answers one or two follow-up questions. If voice interaction is unavailable, a written dialogue or rehearsal with a peer can serve as an alternative.
  4. Make verification part of the task. Students check factual claims against the assigned reading and course sources. They should identify unsupported statements, invented references, or arguments that sound persuasive but do not fit the evidence.
  5. End with a short reflection. Ask students to record which counterargument was strongest, whether they changed or refined their position, and what question they want to raise in class. The reflection should be their own explanation, not an AI-generated summary copied without review.
  6. Bring one prepared contribution to class. Students arrive with a concise claim, evidence, and an open question. The teacher then invites them to build on, challenge, or revise those ideas through live discussion.

A practical first pilot could use an eight-to-ten-minute rehearsal before one seminar each week for several weeks. That duration is a classroom design choice, not a proven optimum: the Columbia study used a purpose-built tool and found that repeated opportunities mattered more than a single exposure. Teachers should adjust the timing to the age of the learners, the complexity of the material, and the available class time.

How to measure whether students are actually speaking up

Counting comments is useful, but it is not enough. A student who makes several short remarks that do not engage with the topic may not be learning more than a student who makes one thoughtful contribution. A small pilot should therefore combine participation counts with a simple measure of contribution quality.

Measure What the teacher can record
Voluntary participation Contributions initiated by students, recorded separately from cold calls or required turns
Evidence use Whether a contribution refers accurately to the reading, data, or course material
Reasoning Whether the student explains why the evidence supports the claim
Response to others Whether the student listens, builds on a peer’s point, or responds constructively to a counterargument
Individual understanding Whether the student can explain the idea independently after the discussion
Student experience A short, optional check-in about confidence, comfort, and perceived usefulness

Record a baseline before introducing the activity. Compare similar lessons where possible, and note attendance, class size, topic difficulty, and changes in teaching approach. Do not treat a rise in the number of comments as proof of improved learning. Review the quality of reasoning and whether students can explain the material without the tool.

For courses where oral performance is itself an assessed outcome, Prowad’s guide to oral assessment in the AI era offers complementary ways to evaluate explanation and understanding. For a different design problem—how AI should be used during group projects rather than individual preparation—see seven design rules for AI in collaborative learning.

What teachers should not infer from this study

  • It does not prove that any chatbot will work. CAiSEY was a purpose-built voice tool tailored to the cases students were preparing. The authors explicitly caution against generalising the result to generic voice chatbots.
  • It does not show that AI is better than a human practice partner. The field experiment did not compare CAiSEY with a structured pre-class conversation with another student or a human tutor.
  • It does not establish a 31% gain in achievement. The measured primary outcome was voluntary class contributions, not exam scores or long-term retention.
  • It does not establish a benefit after one use. The main participation effect appeared after the second assigned opportunity, not immediately after the first.
  • It does not automatically generalise to younger learners. The participants were MBA students in a case-based strategy course. Schools should adapt any trial to learners’ ages, language needs, accessibility requirements, and safeguarding rules.

There are also design limitations. The study was conducted at one US business school, and its participation analysis relied on a smaller observed panel than the 759 students initially randomised. Two course sections did not record cold calls separately, which limited the usable participation data. The authors report that the pattern remained in sensitivity analyses excluding a section with reconstructed attendance, but replication in other subjects, institutions, and age groups is still needed.

Protect student agency, privacy, and access

A well-designed rehearsal activity should prepare students to participate—not create a new requirement to disclose private thoughts to an external platform. Schools should approve the tool, understand what it records, set retention and access rules, and avoid uploading identifiable student information unless the relevant data protections and permissions are in place. If transcripts or reflections are reviewed by teachers, students should be told what is collected and how it will be used.

Provide a non-AI route that meets the same learning objective: a peer rehearsal, a written argument map, or a short conversation with the teacher. Check that students can use the activity with assistive technology and that language or speech-recognition limitations do not unfairly penalise them. The purpose is to widen opportunities to practise, not to make access to classroom participation depend on owning a suitable device or speaking with a particular accent.

For students who already rely on AI to produce complete answers, the activity should emphasise the difference between rehearsal and outsourcing. Prowad has discussed the risk of cognitive offloading in its analysis of an AI study assistant that backfired in a university trial. In this setting, the AI should challenge the learner’s reasoning; it should not write the contribution the learner is expected to make.

The practical lesson: rehearse to participate, not to replace discussion

The Columbia working paper adds a useful dimension to the AI-in-education debate. Instead of asking only whether students get higher scores when they use AI, it examines whether a structured AI activity before class changes what students do when they meet their instructor and peers. Its strongest result is not that a chatbot makes students instantly more talkative. It is that repeated, purposeful rehearsal with a specialised voice partner was followed by more voluntary contributions in later sessions.

Teachers can test this idea without turning the classroom into an AI-led environment. Ask students to think independently, rehearse a position, respond to a counterargument, verify the evidence, and arrive ready to speak. Then judge the activity by the quality of the discussion and the learning students can demonstrate without assistance.

The goal is not more AI conversation for its own sake. It is more meaningful human conversation in class.

Research and source notes

Posted on — Leave a comment

AI in Collaborative Learning: 7 Design Rules for Better Group Work

University students discussing a group project together around a laptop in a classroom

Group projects are changing. Students can now ask a generative AI system to brainstorm, explain a concept, draft a section, critique an argument, or decide which option a team should choose. Used carefully, these capabilities can make collaboration more productive. Used carelessly, they can remove the very exchanges through which students learn to collaborate: explaining ideas, disagreeing with evidence, asking peers for help, and taking shared responsibility.

A report released by the Digital Education Council (DEC) and Pearson on 27 October 2026 makes this tension unusually clear. Drawing on more than 80 global case studies, Designing AI for Collaborative Learning maps 15 emerging approaches and examines how AI can strengthen or bypass seven mechanisms that help groups learn. Its central question is not simply whether AI improves a group’s final product. It is whether students still do the thinking together.

This distinction matters for universities, schools, and professional learning programmes. The goal of AI in collaborative learning should be to improve the quality of peer interaction—not to turn a group assignment into several individual conversations with a chatbot followed by a shared document.

What the new evidence says about AI and student collaboration

The DEC–Pearson report identifies several risks that educators can recognise in everyday group work. Students may arrive at a meeting with similar AI-generated ideas. Some groups ask an AI system to settle disagreements instead of examining competing arguments. AI can also make disengagement harder to notice: a student may submit polished material without having meaningfully participated in the learning process.

The report is a practice-mapping resource, not a randomized trial. Its value is that it draws together more than 80 cases and gives educators a structured way to think about design choices. It should not be read as proof that every AI use reduces collaboration.

Peer-reviewed research offers a more granular picture:

  • A 2026 scoping review: Wei and Perkins examined 18 peer-reviewed studies of generative AI in higher-education group work. The review found possible benefits in idea generation, knowledge development, communication, coordination, reflective thinking, and feedback. It also identified risks involving reduced peer interaction and critical engagement when students over-rely on AI. The authors stressed that outcomes depend on task design, AI literacy, and subject expertise. Read the review in the International Journal for Educational Integrity.
  • A 2025 interaction study: Feng and colleagues analysed a collaborative problem-solving task involving 25 master’s students in six groups. Their network analysis identified a “GAI-centred” pattern: students interacted more with the chatbot than with one another. The study is small and cannot establish what happens in every course, but it shows why teachers should examine interaction patterns, not just the submitted group answer. Read the study in the British Journal of Educational Technology.
  • A 2026 peer-feedback experiment: Chang and colleagues compared peer feedback alone, peer feedback supported by GenAI, and GenAI-supported peer feedback with prompt scaffolding. The 45 student teachers worked in 12 groups. The AI-supported conditions performed better on argumentation measures; the scaffolded condition was particularly helpful for rebuttal evidence and addressing opposing views. The study suggests that AI can improve peer review when it helps students give reasons and suggestions rather than replacing their judgement. Read the open-access study.
  • A 2026 study of AI personas: Jin and colleagues randomly assigned 224 university students to 97 online triads working with no AI, a supportive AI, or a contrarian AI. The contrarian persona produced more challenge-oriented and reflective discussion, but reduced teamwork satisfaction and psychological safety without improving creative performance. This is a short, specific creative task—not evidence that a contrarian chatbot will have the same effect in every class. It does show that productive disagreement needs a supportive group climate. Read the study in the Journal of Computer Assisted Learning.

Together, these sources point to a practical conclusion: AI can contribute ideas, feedback, and structure, but it cannot substitute for the social work of learning. The question for instructors is where AI enters the group process, what it is allowed to do, and which decisions remain with students.

Seven mechanisms that make collaborative learning work

The DEC–Pearson report organises group learning around seven mechanisms. Understanding them helps teachers decide whether a proposed AI use strengthens collaboration or quietly bypasses it.

1. Self-explanation

Students learn when they articulate why they believe something, not merely when they receive a fluent explanation. AI can prompt a learner to explain a claim or identify a missing step. It bypasses self-explanation when it writes the explanation that the student then repeats.

2. Peer modelling

Students learn by seeing how classmates approach a problem, organise evidence, or recover from an error. If every learner works separately with the same chatbot, they may see fewer different human approaches. Ask students to compare methods before consulting AI.

3. Socio-cognitive conflict

Different interpretations can create productive disagreement. AI can introduce a counterargument or a neglected perspective, but it should not act as the final judge. Students should test the counterargument against evidence and explain why they accept, revise, or reject it.

4. Anticipated accountability

When students know that peers will ask them to justify their contributions, they prepare more carefully. AI can help a group generate questions, but it should not become the authority that validates every contribution. Each student should be able to explain the evidence behind their part.

5. Collective scaffolding

Groups make progress when members help one another fill gaps in understanding. AI can suggest a hint or a question that helps a student support a peer. It can also remove the need for peer explanation if it supplies a complete answer too early.

6. Distributed cognition

Complex work becomes manageable when a group shares different parts of the reasoning. AI may handle repetitive formatting or help organise information, leaving students to interpret, compare, and decide. If AI performs the synthesis and judgement as well, the group may have little meaningful work left to do.

7. Socially shared regulation

Effective groups set goals, monitor progress, and adjust their plan together. AI can help the group notice a stalled task or create a progress checklist. The group—not the system—must decide whether to change direction and take responsibility for the result.

Seven design rules for AI-supported group projects

Rule 1: Let students think before they prompt

Begin with a short individual preparation stage. Ask each student to write one initial claim, one piece of evidence, and one question without AI assistance. This gives the group a range of starting points and makes it easier to see whether AI expands or replaces student thinking.

Rule 2: Make peer discussion the first shared step

Do not require every group to consult AI before meeting. Give students time to explain their ideas to one another, identify disagreements, and record what they cannot yet resolve. Only then should they use AI to search for missing perspectives or clarify a difficult concept.

Rule 3: Use AI as a challenger, not an arbiter

Avoid prompts such as “Who is right?” or “Choose the best answer for our group.” Instead ask: “What assumption might this group be overlooking?”, “What evidence would weaken each proposal?”, or “Give us a counterargument that we should test.” Students must decide what survives scrutiny.

Rule 4: Scaffold peer feedback with criteria

Unstructured requests for AI feedback often produce generic praise or a polished rewrite. Give students a feedback frame: identify the claim, check whether the evidence supports it, explain the reasoning that connects them, and offer one counterargument. The 2026 peer-feedback experiment suggests that prompt scaffolding can help students produce more developed argumentation.

Rule 5: Assign AI a bounded role

Specify whether AI is a research assistant, question generator, language editor, rehearsal partner, or process organiser. Do not let the role expand silently into author, evaluator, or decision-maker. A bounded role makes it easier to explain what the system contributed and what students must still do.

Rule 6: Make contributions visible

Use a simple contribution log. Each student records the question they investigated, the evidence they checked, the feedback they gave, and one decision they influenced. The log is not a surveillance tool or a measure of personality; it is a way to make the learning process discussable and to identify uneven participation.

Rule 7: Finish with individual explanation and group reflection

After submission, ask each student to explain one key decision without consulting AI. Then ask the group which disagreement changed its thinking, which AI suggestion it rejected, and what it would do differently next time. This checks individual understanding while preserving the value of collective work.

A 45-minute classroom protocol

The following sequence can be adapted to a seminar, project lesson, or professional training session. It deliberately delays AI until students have exchanged their own ideas.

  1. Individual preparation — 5 minutes: Each learner writes an initial position, evidence, and uncertainty without AI.
  2. Round-robin discussion — 8 minutes: Every member explains one idea. The group records agreements and unresolved differences.
  3. Targeted AI consultation — 7 minutes: The group asks one or two questions designed to reveal alternatives, explain a concept, or identify missing evidence. It does not ask AI to choose the final answer.
  4. Evidence check and debate — 12 minutes: Students verify useful claims, challenge AI suggestions, and decide what to retain or reject.
  5. Joint synthesis — 8 minutes: The group writes its conclusion and records the reasoning behind its main decision.
  6. Individual exit reflection — 5 minutes: Each student states what they learned from a peer and identifies one AI suggestion they accepted or rejected, with a reason.

How to assess collaboration without rewarding polished AI output

A polished presentation is not enough to show that a group learned together. Assessment should combine the quality of the final work with evidence of the process and each learner’s understanding.

What to assess Evidence to look for
Reasoning Claims supported by relevant evidence and clear explanations
Peer interaction Students respond to, question, and build on one another’s ideas
Constructive disagreement The group considers counterarguments and explains its final decision
AI judgement Students verify, adapt, or reject AI suggestions with reasons
Individual learning Each student can explain a key concept or decision independently
Shared responsibility Contributions and responsibilities are visible and reasonably distributed

These criteria should be adapted to the discipline and age of the learners. A short contribution log, peer reflection, or individual oral question may be enough; continuous monitoring of private conversations is rarely necessary and can undermine trust.

What institutions should put in their AI group-work guidance

Institutional rules should be specific enough to shape behaviour. A broad statement that “AI may be used responsibly” does not tell students whether they may use it to brainstorm before a meeting, draft a shared answer, evaluate a peer’s contribution, or resolve a disagreement.

A useful course-level agreement should answer five questions:

  • When may AI be used? For example, after an initial individual contribution or after the group has identified a genuine information gap.
  • What may AI do? List permitted roles such as generating alternatives, explaining difficult concepts, or checking clarity.
  • What must remain human? Require students to own the final judgement, evidence selection, and explanation.
  • How will use be disclosed? Ask groups to record material AI contributions in a short, proportionate note.
  • How will learning be assessed? Combine the group product with peer interaction, individual explanation, and reflection.

These rules complement—not replace—broader institutional policies on privacy, academic integrity, accessibility, and approved tools. For a wider framework on school-level adoption, see Prowad’s five-step AI integration framework and the guide to AI assessment design in higher education. For the distinction between collaboration with an AI system and collaboration among learners, our article on four models of teacher–AI collaboration provides a related but different perspective.

What the evidence cannot yet tell us

The evidence base is promising but still developing. The 2026 scoping review included 18 studies and searched literature only through March 2025. The 2025 interaction study involved six small groups. The peer-feedback experiment involved 45 student teachers. The study of AI personas used a brief online creative task. These designs help explain possible mechanisms, but they do not establish a universal effect across disciplines, age groups, or long-term courses.

The DEC–Pearson report adds breadth through more than 80 case studies and 15 emerging methodologies, but a case-based map is not the same as a controlled evaluation of learning gains. Institutions should therefore pilot specific designs, compare them with a clear baseline, and measure both group interaction and individual learning over time.

Conclusion: Keep the group at the centre

AI in collaborative learning is not simply a question of whether students should be allowed to use a chatbot during group work. It is a design question: does the tool help students explain, question, challenge, coordinate, and learn from one another—or does it perform those activities on their behalf?

The strongest approach is to preserve a human sequence: students think individually, exchange ideas with peers, consult AI for a bounded purpose, test its suggestions, and take responsibility for the final decision. When assessment also values reasoning, peer interaction, and individual understanding, AI can become a resource for collaboration rather than a substitute for it.

The practical test is simple: after the AI has been used, can every member explain what the group decided, why it decided it, and how another student’s thinking changed their own?

Research and source notes

Posted on — Leave a comment

AI Vendor Contracts for Schools: 10 Clauses to Check Before Signing

Two professionals reviewing paperwork at a conference table with a laptop during an education technology procurement meeting

An AI tutor, writing assistant, assessment generator or classroom chatbot is not just another software subscription. It may process student prompts, essays, grades, voice recordings, disability-related information and interaction histories. The contract decides what the provider may do with that information, which other companies can access it, how long it remains stored and what happens when the school wants to leave.

That is why AI vendor contracts for schools deserve a separate review before a tool is approved for students. A product can look useful in a demonstration and still have terms that leave a school with little control over student data.

A timely development makes this issue more concrete. Beginning 1 November 2026, Microsoft says US school districts can add the AFT/UFT AI Safety & Privacy Standard to new or existing Microsoft agreements, without waiting for renewal or renegotiating the full contract. The protections become contractually enforceable when incorporated into the agreement. This is a significant vendor-specific step, not a rule that automatically covers every AI provider or every school worldwide. (Microsoft fact sheet; full 31-page standard)

Why school AI procurement is now a governance issue

The contract question is not simply whether a provider says it is secure. Schools need to know what data enters the system, why it is processed, whether prompts or outputs can be used to improve models, which subprocessors receive information, and whether administrators can verify the answers.

Research on educational technology procurement has repeatedly identified a gap between adopting tools and governing their data practices. A peer-reviewed study in the Journal of Consumer Affairs found a privacy-security chasm in K–12 technology adoption, drawing on interviews and public state reports. The authors argue that schools’ technology decisions can expose children to risks that are not always visible to the people selecting the products. (Walker et al., 2023)

A 2024 study of Canadian colleges and universities found that privacy, security, accessibility and care-of-data practices were important procurement considerations, but standards were not yet used in a consistently structured way. Its sample was small—10 institutions across six provinces—so it should be read as an exploratory environmental scan, not a representative estimate of every institution. (Ali, Prompiengchai & Joordens, 2024)

The practical implication is straightforward: schools should turn broad privacy promises into written, testable obligations. The following ten clauses provide a starting checklist for reviewing an AI data processing agreement (DPA), licensing agreement or procurement addendum.

10 clauses to check before signing an AI vendor contract

1. Define exactly what counts as school and student data

Do not define protected information as names and grades alone. AI products can process prompts, uploaded files, generated answers, voice and video, interaction logs, device identifiers, location information, saved memories and metadata. A student’s essay may contain personal details even when the student has not typed a name.

Ask the vendor for a data map that lists each category collected, its purpose, where it is processed, who can access it and how long it is kept. The contract should also distinguish genuinely de-identified operational telemetry from information that can still be linked to a learner. If the provider cannot explain the data flow in plain language, the school cannot meaningfully assess the risk.

2. Restrict purposes and prohibit model training on covered data

Write down the only purposes for which the provider may process school data: delivering the contracted service, maintaining security and other specifically authorised functions. Avoid vague permissions such as “improving our services” unless the agreement defines exactly what that means.

For student and educator information, request an explicit prohibition on using prompts, uploads, responses, records or derived data to train, fine-tune, benchmark or otherwise improve general AI models. The AFT/UFT standard takes this approach, with a narrowly defined exception for certain safety and security processing. If a vendor needs an exception, the contract should limit it to the minimum necessary data, a specific safety purpose, a defined retention period and auditable records. It must not become a back door for general model improvement.

3. Establish data ownership and the school’s legal role

State who owns student work, educator-created materials, prompts, outputs and institutional records. The provider should receive only the limited rights needed to deliver the service; it should not gain a broad licence to sell, advertise with, disclose or reuse school content.

The agreement should also identify the parties’ roles under the applicable privacy regime—for example, whether the school is the controller and the provider is a processor, or whether the provider determines some purposes independently. Those roles cannot be settled by a label alone: they must match what the parties actually do. Have the school’s data protection officer or qualified counsel review the lawful basis, notices and any required consent arrangements in the relevant jurisdiction.

4. Minimise collection and control high-risk features

The product should collect only the information necessary for the educational task. Ask whether optional features such as persistent memory, behavioural profiling, biometrics, precise location tracking, emotion inference or continuous attention monitoring can be disabled.

For younger learners, require age-appropriate settings and a clear explanation of how parental notice or consent is handled where the law requires it. A feature that is switched on by default can still create risk even if a school never intended to use it. Specify which settings the school administrator controls and whether the provider can change them remotely.

5. Name subprocessors and disclose data locations

Many AI services depend on external model providers, cloud hosts, analytics services and content-safety vendors. The school should receive a current list of subprocessors, what each one does, which data categories each receives and the countries or regions where data is stored and processed.

Require every subprocessor to be bound by protections at least as strong as the main contract. The provider should give advance notice before adding or replacing a subprocessor, explain material changes and offer a workable objection or termination route where the change creates a legitimate privacy or security concern. A statement that data may be shared with “trusted partners” is not enough.

6. Set retention, export and deletion rules—including backups

Specify retention periods for prompts, outputs, uploaded files, account records, safety logs, memory files and backups. Define what happens when a student leaves, a class ends, the pilot expires or the school terminates the service. Require export in a usable, documented format and written confirmation when deletion is complete.

Do not assume that pressing a delete button removes every copy. The AFT/UFT standard, for example, sets a defined deletion process and allows up to 180 days for deletion from active systems and backup copies in specified circumstances. That is a feature of that particular agreement, not a universal best-practice deadline. Schools should negotiate a period proportionate to the data and service, and clarify exceptions for legal holds or narrowly limited security investigations.

7. Make security and breach response measurable

Replace general assurances such as “industry-standard security” with evidence and obligations: encryption in transit and at rest, role-based access, least-privilege permissions, multi-factor authentication for privileged access, independent penetration testing, vulnerability management and a documented incident-response plan.

Set a clear breach-notification deadline, explain when the clock starts, identify the contacts who must be notified and require updates while the incident is investigated. The AFT/UFT standard specifies notification within 72 hours after awareness of a confirmed or reasonably suspected breach involving covered data. A school should use the applicable legal deadline where it is stricter, and should not treat 72 hours as a universal legal rule.

8. Keep people responsible for consequential decisions

AI may help teachers organise information or generate suggestions, but the contract should not allow the system to make consequential decisions about discipline, placement, special-education referrals, student risk classifications or employee evaluation without meaningful human review and authority to override the result.

Require the provider to explain the system’s intended use, known limitations, likely failure modes and the evidence behind high-impact claims. Define who investigates a disputed output, how it can be corrected and how affected learners or families can raise a concern. If the product includes agentic features that can send messages, submit work or take other actions, specify which actions are disabled by default and which require explicit approval.

9. Require transparency, accessibility and evidence of fairness

Ask for a plain-language explanation of how the AI feature works, what data it uses, what it cannot reliably do and how users can recognise AI-generated output. Require accessible design, including support for assistive technologies, captions, keyboard navigation and appropriate language support.

For systems used with diverse learners, request evidence about accuracy and performance across relevant groups, including students with disabilities and multilingual learners. The contract should provide a channel for reporting bias, accessibility failures or harm, and a process for the provider to investigate and remedy them. UNICEF’s 2025 Guidance on AI and Children places privacy, safety, fairness, transparency, inclusion and children’s best interests among its core requirements.

10. Control product changes, audits, exit and remedies

An AI product can change after procurement: the provider may switch models, introduce memory, add a chatbot, connect a new subprocessor or change how prompts are retained. Require advance notice of material changes and a right to review the privacy impact before those changes are enabled for students. The school should be able to disable a feature or pause deployment while a serious concern is assessed.

Include audit or assurance rights proportionate to the service, access to relevant certifications and reports, data portability, transition assistance and termination rights for material or repeated breaches. The provider should remain responsible for its subprocessors. Make sure the contract identifies which document prevails if the main terms, privacy addendum and product terms conflict.

Questions to send to an AI vendor

Before approving a tool, ask the provider to answer these questions in writing and attach the answers to the procurement record:

  • What exact student, educator and institutional data does the product collect, including prompts, outputs, logs and memory?
  • Will any covered data be used to train, fine-tune, evaluate or improve a model? If an exception exists, what precise purpose and controls limit it?
  • Which model providers and subprocessors receive the data, and where is it processed?
  • How long are active data, logs and backups retained, and how is deletion certified?
  • Can the school disable memory, profiling, tracking and agentic actions?
  • What independent security evidence, accessibility testing and fairness evaluations can the vendor provide?
  • What happens if the product changes materially, suffers a breach or fails to meet the contract?
  • Can the school export its records and leave without a technical or financial penalty?

If the answers are vague, inconsistent with the privacy policy or available only in marketing material, treat the issue as unresolved. A pilot should not be used to bypass procurement: where student data is involved, the necessary privacy and security terms should be in place before the data is uploaded.

How the checklist fits different legal systems

The Microsoft/AFT example is a useful contract model, but it is specific to participating products and US school agreements. Other jurisdictions should adapt the clauses to their own laws rather than copy US terminology.

  • European Union: the European Commission’s Public Buyers Community provides model contractual clauses for high-risk AI and a lighter, customisable version for non-high-risk AI. These are procurement templates, not a substitute for legal review or the EU AI Act and data-protection obligations. Explore the EU model clauses.
  • United Kingdom: the Department for Education’s EdTech procurement guidance, updated on 14 October 2026, recommends early DPO involvement, data minimisation, impact assessment for high-risk processing and clear contractual responsibilities for subprocessors, deletion, breach notification and staff access. Read the guidance.
  • Morocco: on 8 June 2026, the Higher Council for Education, Training and Scientific Research published a recommendation calling for a national framework to guide AI use in education, training and research. It highlights institutional responsibility, equity, learning quality and the human role in education; it is a policy recommendation, not itself a vendor-contract law. Read the Council’s recommendation.
  • Internationally: UNESCO’s guidance on generative AI in education and research and UNICEF’s child-centred AI guidance provide principles for privacy, age-appropriate use, human agency and children’s rights that can inform local procurement requirements.

A practical approval sequence for schools

  1. Define the use case. Identify the learning or administrative problem and the people who will use the system.
  2. Map the data. List what students and staff may enter, what the tool generates, and where each item goes.
  3. Review the contract. Have procurement, IT/security, the DPO, safeguarding staff and educational leaders review the same written terms.
  4. Test with dummy data first. Check usability and educational value without exposing identifiable student information.
  5. Approve a limited pilot. Set success criteria, approved users, age groups, data limits, human oversight and a review date.
  6. Reassess after changes. Keep a record of model, feature, subprocessor and retention changes, and renew staff guidance when the product changes.

Schools should also connect procurement with their wider AI use policy, their process for evaluating AI learning tools and safeguards for AI monitoring of teachers. A contract cannot decide whether a tool improves learning, but it can establish the boundaries within which a school tests that question responsibly.

The bottom line

A school AI contract should be judged by what it makes enforceable, not by how reassuring the vendor’s privacy page sounds. Define the data, limit its use, control subprocessors, set deletion rules, require security evidence, preserve human oversight and secure a practical exit route. The November 2026 Microsoft/AFT development shows that these protections can be written into commercial agreements. The next step for every school is to make its own requirements explicit before student data enters an AI system.

This article is an educational procurement checklist, not legal advice. Contract language, consent, data residency and retention requirements must be reviewed against the laws and procurement rules that apply to the school.

Sources and further reading

Posted on

AI for Reading Comprehension: 5 Ways to Build Deep Reading

Students reading together around a table, illustrating focused reading and discussion

Students can ask an AI chatbot to explain a difficult paragraph, define unfamiliar words or generate questions about a text. Those uses can make reading more accessible. But when a chatbot replaces the act of reading—by summarising the assigned chapter before a student has opened it—the learner may finish the task without developing the comprehension skills the task was meant to build.

New international evidence makes this distinction especially important. The OECD’s PISA 2025 Results, released on 8 September 2026, documents a continuing decline in reading performance and a rise in rushed, inaccurate reading. At the same time, a 2026 network meta-analysis of 56 studies finds that the reading medium matters: paper generally supports comprehension better than small screens that require scrolling. Together, these findings point to a practical question for schools: how can teachers use AI for reading comprehension without allowing it to do the reading for students?

What the PISA 2025 reading results actually show

PISA 2025 assessed more than 760,000 students across 91 countries and economies. Across OECD countries, average reading performance fell by 14 points between 2022 and 2025, and by 28 points between 2015 and 2025. The OECD also reports that the proportion of students classified as “hasty readers”—those who answer quickly but inaccurately—increased from 6.6% in 2018 to 11.4% in 2025. The share of accurate, fluent readers declined by seven percentage points over the same period.

The difficulty is not simply that students cannot locate a fact in a short passage. OECD analysis identifies particular weaknesses in tasks involving longer texts, evaluating information and connecting evidence across sources. These tasks require readers to hold ideas in mind, compare claims, infer meaning and decide whether a source is credible. They are precisely the processes that can be bypassed when a student accepts an AI-generated summary as a substitute for the original text.

These results do not prove that AI caused the decline in reading. PISA describes a complex picture involving reading habits, digital distraction, school conditions and wider social changes. The responsible conclusion is narrower: schools need to protect sustained reading and critical evaluation while teaching students how to use AI deliberately.

AI use is widespread—but frequency is not the same as learning

The same PISA cycle asked students how they used AI chatbots for schoolwork. On average, 46% of students in OECD countries reported using chatbots to help them learn at least weekly. The OECD found that students who used AI moderately for general learning purposes tended to perform slightly better than those who used it rarely or very intensively. Students who used AI very frequently or only occasionally tended to score lower than non-users in the relevant comparisons.

This is an observational relationship, not proof that a particular level of AI use produces better or worse results. Students differ in prior knowledge, motivation, school context and reasons for turning to a chatbot. The OECD itself cautions against interpreting these patterns as causal effects. For teachers, the useful message is that purpose and instructional guidance matter more than access alone.

For a broader look at the same PISA evidence on student chatbot use, see our analysis of PISA 2025 AI use in schools. This article focuses on a different question: how to design reading activities so that AI supports comprehension rather than replacing it.

Why the reading medium still matters

AI-supported reading often happens on a phone or laptop, but the screen itself can change the reading experience. A 2026 open-access network meta-analysis by Virginia Clinton-Lisell and Christine Litzinger compared paper with computers, tablets, e-readers and smartphones. It synthesised 56 independent studies and 79 effect sizes.

Across the comparisons, paper ranked highest for reading comprehension, followed by tablets, e-readers, computers and smartphones. The most important qualification was scrolling: when students had to scroll through a text, paper showed a meaningful comprehension advantage over digital devices. When scrolling was not required, the differences between paper and digital formats were small and not statistically reliable.

This does not mean that every student should read every text on paper. It suggests a practical design choice: use a stable, paginated layout for longer or more demanding texts, avoid forcing students to navigate long passages through continuous scrolling, and let students choose a suitable format when the learning objective allows it. The 2025 meta-analysis on leisure digital reading and comprehension also indicates that the relationship between digital reading habits and comprehension is nuanced, rather than a simple claim that all screen reading is harmful.

Five ways to use AI for reading comprehension without outsourcing the reading

1. Make the first encounter with the text independent

Before opening an AI tool, ask students to read the passage themselves. They can underline the central claim, mark two unfamiliar terms and write one question in the margin. This short independent first pass gives the learner something to compare with the chatbot’s explanation. It also gives the teacher evidence of what the student noticed before receiving assistance.

For a challenging text, the first pass does not need to produce a polished summary. A rough annotation is more useful than a fluent answer generated by a machine because it reveals the learner’s initial understanding.

2. Use AI to clarify a barrier, not replace the passage

Students can ask an AI reading tutor to explain one sentence, define a term in context or unpack a difficult reference. Keep the question narrow. For example:

“Explain the meaning of this paragraph in simpler language, but do not summarise the whole text. Identify the sentence that supports your explanation, and tell me which words in the original passage carry the main idea.”

The student should then return to the original passage and check whether the explanation is accurate. If the chatbot invents context or misreads the author’s position, the discrepancy becomes a useful lesson in verification.

3. Turn summaries into questions that require evidence

Instead of asking AI to write the summary students will submit, ask it to generate three comprehension questions at different levels: one about explicit information, one about inference and one about evaluating the author’s evidence. Students answer in their own words and cite the relevant paragraph or sentence.

This shifts the tool from answer production to question generation. It also helps teachers distinguish between locating information and the deeper work of interpreting and evaluating it—an important distinction in the OECD’s reading analysis.

4. Compare sources rather than accepting one fluent response

For older students, provide two short sources that disagree or emphasise different evidence. Ask the AI to list the claims made by each source, then require students to verify every claim against the originals. They should identify what the sources agree on, where they differ and what information is missing.

The final judgement must belong to the student. A chatbot can help organise a comparison, but it cannot replace the learner’s responsibility to assess authorship, evidence, date, purpose and reliability. This activity also builds the information-evaluation skills that matter beyond school assignments.

5. Close the chatbot and retrieve the meaning

After the AI-supported stage, students should put the tool away and reconstruct the argument from memory. They might write a three-sentence explanation, draw a concept map, answer a new question or explain the text orally to a partner. The teacher can then compare this independent response with the student’s earlier annotations.

Retrieval is important because recognising an AI explanation is not the same as being able to recall and use the underlying idea. Our guide to AI and student memory explores how retrieval practice can protect learning when digital tools are available.

A short classroom routine teachers can use tomorrow

For a 30-minute lesson built around a 500–700-word text, try this sequence:

  1. Minutes 0–7: Students read independently, annotate the main claim and mark one point of confusion.
  2. Minutes 7–12: Students use AI to clarify one selected passage, then verify the explanation against the source.
  3. Minutes 12–20: Students answer an inference question and an evidence-evaluation question, citing the text.
  4. Minutes 20–26: Students close AI and write a short explanation from memory or discuss it with a partner.
  5. Minutes 26–30: The teacher checks a sample of responses and asks students to explain which evidence changed or strengthened their interpretation.

For a high-stakes or individual assessment, add a brief oral explanation or an in-class annotation check. Our article on oral assessment in the AI era offers practical formats for checking what learners can explain independently.

What the Morocco data add to the discussion

The OECD’s Morocco country note makes the issue concrete. In PISA 2025, 13% of students in Morocco reached at least Level 2 proficiency in reading, compared with an OECD average of 69%. The note also reports that 45% of Moroccan students used AI chatbots to help them learn at least weekly, while 30% used them to summarise a text they had to read. These figures describe reported behaviour and proficiency; they do not show that chatbot use caused the reading results.

The implication is not to reject AI. It is to ensure that students who use AI frequently still receive regular opportunities to read complete texts, explain ideas without assistance, compare evidence and ask teachers or classmates for help. AI should widen access to explanation without narrowing the amount of thinking students do themselves.

How schools can tell whether AI is helping

Schools should evaluate reading outcomes, not simply count chatbot logins or the number of AI-generated activities. A small set of indicators can make implementation more meaningful:

  • Independent comprehension: Can students answer a comparable question without AI after the activity?
  • Evidence use: Do they cite accurate details from the original text rather than repeat a chatbot’s unsupported claim?
  • Inference and evaluation: Can they explain why an interpretation is stronger and assess the credibility of a source?
  • Transfer: Can they apply the same strategy to a new text that the chatbot has not summarised?
  • Equity and access: Do students with different reading levels, languages and device access benefit from the routine?

Teachers should also explain to students that AI can make confident mistakes, omit qualifications or flatten an author’s argument. A useful classroom norm is simple: every AI explanation about a text must be checked against the text itself.

The principle: AI should deepen the encounter with a text

The PISA 2025 reading findings are a warning against confusing fast task completion with deep comprehension. The evidence on digital reading adds a reminder that format and navigation can influence how carefully students process longer material. Neither source justifies a blanket ban on AI or screens. Both support more deliberate instructional design.

Used well, AI can make a difficult paragraph more accessible, generate questions, support vocabulary and help students compare interpretations. Used poorly, it can remove the very cognitive work that reading lessons are designed to develop. The test of a successful AI-supported reading activity is therefore not whether the chatbot produced a good summary. It is whether the student can understand, question, explain and transfer the meaning after the chatbot is closed.

Sources and further reading

Posted on — Leave a comment

Generative AI in Programming Education: What 46 Studies Reveal

Computer science students learning programming on laptops in a university classroom

Generative AI can now explain a programming concept, suggest code, identify a likely bug, and produce a working example in seconds. That changes the practical conditions under which students learn to program. It does not, by itself, answer the educational question: can a learner design, explain, test, and repair a program without the assistant?

A systematic review published in September 2026 mapped 46 peer-reviewed empirical studies of generative AI in higher-education programming courses. A second, more recent field evaluation followed 357 learners using a teacher-governed adaptive large language model (LLM) tutor. Read together, these sources point to a useful distinction: AI can make practice and feedback more available, but stronger formative activity is not automatically the same as stronger independent achievement.

This guide explains what the research can and cannot establish, then turns it into a practical design for instructors teaching Python, Java, or introductory computing. The goal is not to ban coding assistants or let them complete every task. It is to make AI support visible, bounded, testable, and gradually less necessary.

What the 46-study review reveals about generative AI in programming education

Yalçın, Bakır-Yalçın, İslamoğlu, and Ursavaş published Mapping Research on Generative Artificial Intelligence for Programming Education: A Systematic Review in the Journal of Computer Assisted Learning on 21 September 2026. Following PRISMA guidelines, the authors analysed 46 peer-reviewed empirical studies in higher education.

Several patterns matter to course designers:

  • ChatGPT dominated the reviewed research. It appeared in 76% of the studies. This describes the literature reviewed, not the share of all students or institutions using ChatGPT.
  • Java and Python were the most frequently studied languages. The evidence therefore speaks most directly to common university programming contexts, not every language, age group, or vocational setting.
  • The research was geographically broad but still exploratory. Studies came from 28 countries, while nearly 70% appeared in conference proceedings.
  • More than half of the studies lacked an explicit pedagogical framework. This is a central weakness: tool use is easier to describe than the learning theory and instructional sequence that should guide it.
  • Reported benefits included engagement, feedback, and learning support. The review also identified concerns about over-reliance, weaker conceptual understanding, and academic integrity.

The review does not justify a universal claim that AI improves programming achievement. It maps a growing and varied research field. Different studies use different tasks, tools, measures, course designs, and comparison conditions. A student finishing a coding exercise faster is not necessarily learning the concepts more deeply.

Why faster code completion is not the same as learning to program

Programming competence combines several capabilities: understanding a problem, decomposing it into steps, choosing data structures, writing syntax, predicting behaviour, testing edge cases, locating faults, and explaining design decisions. A generative model can help with some of these activities, but it can also conceal which parts the student can perform independently.

Consider a beginner who asks an assistant to write a loop. The returned code may run correctly. Yet the student may not understand the loop condition, why the variable changes, what happens at the boundary, or how to diagnose an off-by-one error. The completed task is evidence of a working program; it is not sufficient evidence of the learner’s mental model. A June 2026 scoping review of generative AI for computational-thinking education identified the same tension: beginners may offload too much thinking, while advanced learners may underuse AI in complex projects. Its authors proposed seven design guidelines rather than a one-size-fits-all tool rule (Ouaazki et al., 2026).

There is an opposite risk too. If a course prohibits every AI interaction, students may lose opportunities to compare explanations, receive timely debugging hints, or learn how to evaluate generated code responsibly. The instructional choice is therefore not simply use versus no use. It is which assistance is permitted at which stage, for what learning purpose, and with what evidence of independent understanding.

What a field evaluation of 357 learners adds

A study by Pavel Bartoš, Adaptive large language model scaffolding supports online programming education through learning analytics and knowledge tracing, was published in Discover Education on 17 September 2026. It evaluated a low-stakes design combining a map of programming knowledge components, learning analytics, teacher-authored recommendations, a constrained LLM tutor, and explainable records.

The field evaluation included 357 consenting learners, 8,568 pre- and post-assessment item records, 6,532 formative events, and 1,168 assistant sessions. The study compared adaptive and comparison conditions using the same core materials and assessments. The authors note that missing archival details required the findings to be interpreted quasi-experimentally rather than as a definitive randomised causal test.

The adjusted difference on the primary post-test outcome was 3.07 percentage points, with a 95% confidence interval from -0.87 to 7.02 and p = .127. That result was not statistically significant. Adaptive learners showed a small raw-gain advantage (Hedges g = 0.21) and stronger formative and survey indicators, but course completion was unchanged.

This is a useful corrective to exaggerated claims. Teacher-governed AI scaffolding may help learners practise, seek help, and feel supported. In this study, however, those process signals did not translate into a statistically significant improvement in the primary final assessment. The authors recommend keeping such systems transparent, auditable, and low-stakes—not treating them as authorities for grading or certifying mastery.

A new programming pedagogy model: useful proposal, not yet a proven intervention

On 28 October 2026, Bringula and Heintz published a perspective article in Frontiers in Artificial Intelligence, Large language model-assisted modern programming pedagogy model: a perspective on teaching programming in the era of LLMs. It proposes the LLM-Assisted Modern Programming Pedagogy (LAMPP) model.

The model connects four parts of programming pedagogy—teaching, lesson design, learner engagement, and assessment—with ethics as a cross-cutting concern. It draws on constructivism, social constructivism, cognitive apprenticeship, and self-regulated learning. Its central idea is that the educational value of an LLM depends on how teachers orchestrate the activity, not on the presence of the tool alone.

Because this is a perspective paper proposing a framework, its mechanisms should be treated as design propositions for educators and researchers to test, not as experimentally confirmed effects. It is nevertheless consistent with the systematic review’s finding that many studies have not made their pedagogical assumptions explicit.

Six ways to use AI coding assistants without outsourcing the learning

1. Require a first attempt before the assistant responds

Ask students to write a short plan, pseudocode, flowchart, or initial solution before opening an AI assistant. The first attempt gives the learner something to compare with the generated suggestion and gives the teacher evidence of prior reasoning. For a beginner’s Python exercise, the student might identify the inputs, expected output, and sequence of operations before requesting a hint.

2. Ask for a hint or explanation, not a complete solution

Teach students to request one next step: explain an error message, define a concept, suggest a test case, or point to the relevant line without rewriting the whole program. Instructors can provide a set of approved prompt patterns. The aim is to keep the learner responsible for deciding what to change and why.

3. Make debugging a reasoning task

When a program fails, students should state what they expected, what actually happened, and which evidence narrows down the cause. An assistant may suggest possible faults, but the student should verify each suggestion by inspecting the code, running a test, and explaining the result. This turns debugging from copying a patch into a repeatable problem-solving process.

4. Compare generated code against tests and requirements

Ask students to review AI-generated code for correctness, readability, edge cases, security, and alignment with the assignment. Require at least one test that the generated solution initially fails or one change the student can justify. A plausible answer is only a hypothesis until it has been tested against the specification.

5. Fade assistance as competence develops

Early practice may permit conceptual explanations and small hints. Later tasks can restrict AI to documentation lookup or debugging questions, followed by an independent exercise. The amount of support should respond to the learner’s demonstrated understanding, not simply to a fixed number of weeks or prompts.

6. Assess the process as well as the final program

Use short code walkthroughs, live modifications, oral explanations, debugging demonstrations, and project reflections alongside submitted files. Ask a student to change one requirement and explain which parts of the program must change. These methods do not need to become high-pressure oral examinations; short, low-stakes checks can reveal whether the student understands the code they submitted.

A practical lesson sequence for an introductory programming class

  1. Set one observable objective. For example: students will use a loop to process a list and explain how the loop terminates.
  2. Model the concept without AI first. Demonstrate a small example and ask learners to predict the output before running it.
  3. Give students an independent attempt. Collect their pseudocode or first version so that later changes can be interpreted.
  4. Allow bounded AI support. Students may ask for a hint, explanation, or test case, but not request a complete submission. They record what they asked and what they accepted or rejected.
  5. Require verification. Students run normal, boundary, and invalid-input tests where relevant, then explain at least one decision they made.
  6. Finish with an unaided transfer task. Change the input, add a condition, or ask students to trace a similar program without the assistant.
  7. Review and adjust. Compare the independent work with the initial attempt, discuss common errors, and refine the AI-use rules for the next lesson.

How to assess programming learning when AI is available

A balanced assessment should separate the quality of the program from the learner’s ability to explain and adapt it. One practical rubric can score each dimension from 0 (not yet demonstrated) to 2 (demonstrated independently):

  • Problem decomposition: Can the student translate the task into steps and identify relevant inputs and outputs?
  • Conceptual explanation: Can the student explain why the algorithm and key constructs work?
  • Testing and debugging: Can the student design a useful test, interpret an error, and justify a repair?
  • Adaptation: Can the student modify the program when a requirement changes?
  • Responsible AI use: Can the student disclose assistance, check generated suggestions, and identify code they do not understand?

This is a suggested classroom rubric, not a validated scale from the cited studies. Teachers should adapt it to the course outcomes and test whether different assessors can apply it consistently. A code detector should not replace direct evidence of competence or a fair opportunity for students to explain their work.

What institutions should monitor before scaling AI in programming courses

Start with a limited pilot rather than a campus-wide mandate. Record the model and version used, permitted functions, prompt guidance, data handling, and any changes made during the course. Keep student code and conversation logs only when necessary, explain the purpose, restrict access, and follow institutional privacy requirements.

Measure more than tool activity. Useful indicators include independent test performance, the ability to explain and modify code, quality of debugging, completion of formative practice, student help-seeking, teacher workload, and differences in access or outcomes across learner groups. Compare the AI-supported sequence with a credible alternative where possible. If the design is not randomised or the sample is small, report associations and limitations rather than causal conclusions.

Teachers need professional development to inspect AI outputs, design tasks that preserve student reasoning, recognise common failure modes, and make transparent decisions about acceptable assistance. Students also need to evaluate AI outputs critically; see Prowad’s guide to what AI literacy means for a broader framework. For broader institutional evaluation, see Prowad’s evidence checks for AI learning tools. For a related example of chatbot design that elicits reasoning rather than simply supplying answers, read AI chatbots for higher-order thinking in STEM.

Conclusion: teach students to work with AI—and without it

The 46-study review shows that generative AI has become a significant research topic in programming education, but the evidence base remains uneven and often lacks an explicit pedagogical framework. The 357-learner field evaluation suggests that teacher-governed scaffolding can strengthen formative practice and perceived support without necessarily improving the primary final assessment. The recent LAMPP perspective offers a coherent way to think about teaching, lesson design, engagement, assessment, and ethics, but its proposals still need testing.

For instructors, the practical direction is clear: make an independent attempt visible, use AI for bounded explanations and debugging support, require verification, gradually reduce assistance, and assess transfer without the tool. The measure of success is not how much code an assistant can generate. It is whether students become more capable of understanding, testing, adapting, and defending the programs they create.

References

Posted on — 2 Comments

Oral Assessment in the AI Era: 5 Practical Designs

Teacher speaking with a student at a classroom desk during an individual learning check

Generative AI has made a familiar assessment problem harder to ignore: a polished essay, solution or presentation may show what a learner can produce with a chatbot, but not necessarily what the learner understands. In response, some teachers are moving parts of assessment back into the classroom through short oral examinations, supervised writing, live demonstrations and follow-up questions.

A Reuters report published on 28 October 2026 describes teachers replacing some take-home essays with brief oral checks, asking students to explain mathematical methods and using live projects to make reasoning more visible. These are examples of a wider reassessment shift, not proof that every school should abandon written work.

The practical question is not whether oral assessment can make learning “AI-proof.” No format can guarantee that. It is whether a teacher can collect more direct, varied and fair evidence of a student’s understanding. This guide explains five formats, a simple scoring rubric, accessibility safeguards and a low-risk way to pilot oral assessment in the AI era.

What oral assessment can reveal—and what it cannot

An oral assessment asks learners to explain, interpret, justify or apply knowledge in a conversation or live demonstration. The teacher can ask a follow-up question, change a condition, request an example or invite the learner to compare two approaches. That makes it possible to observe parts of the learner’s reasoning that may be hidden in a finished written product.

For example, after a student submits a solution, a teacher might ask: “Why did you choose this method?”, “What would change if this value doubled?” or “Show me where your reasoning could fail.” The aim is not to catch a learner out. It is to see whether the student can explain the choices behind the answer and respond to a new but related prompt.

However, a short conversation is only one sample of performance. It does not prove that a learner never used AI, establish long-term retention, or provide a complete picture of complex writing and research skills. Oral evidence should be combined with drafts, written work, practical tasks, quizzes, observation and later checks where appropriate.

A useful research example is The Conversational Exam, a January 2026 paper listed by Stanford’s SCALE Initiative. Its authors describe a format in which students code live while explaining their reasoning. The pilot involved 58 students in small groups over two days. It is an arXiv preprint and a small implementation study, not a large controlled trial or proof that oral examinations will scale equally well in every subject.

Five practical oral assessment formats

1. The three-minute concept check

Ask each learner to explain one important concept in their own words, give an example and identify a common misconception. Keep the prompt aligned with a learning objective rather than asking for a broad speech. In a science lesson, a learner might explain why a result supports one hypothesis more than another. In history, the learner might distinguish a cause from a consequence and support the distinction with evidence.

This format works well as a low-stakes formative check. It can be conducted with a rotating sample of learners during a lesson, or as a short follow-up after a written task. A brief check should inform teaching, not become a high-stakes grade on its own.

2. The oral defence of submitted work

After a project, essay, design or problem set, invite the learner to explain two or three decisions they made. Ask about a source, a revision, a calculation or a rejected alternative. If AI use was permitted, the learner can describe what the tool contributed, what they changed and how they verified the result.

Use the same core prompts for all learners, with one or two tailored follow-ups. This reduces the risk that one student receives a much harder conversation than another. The purpose is to understand the work’s provenance and the learner’s judgement, not to demand that students memorise every sentence they submitted.

3. The “why this method?” problem interview

Give students a problem with more than one defensible approach. Ask them to choose a method, explain why it fits and identify a limitation. Then vary one condition: change a number, introduce a new constraint or ask what would happen if an assumption were false.

This is especially useful in mathematics, science, computing and vocational training. A student who can only repeat a memorised procedure may struggle when the conditions change; a student who understands the method should be able to explain which parts remain valid and which need revision.

4. The paired explanation or structured dialogue

Ask learners to explain an idea to a partner, compare two interpretations or challenge a claim using evidence. The teacher listens for the quality of reasoning, not simply the number of times a learner speaks. A short individual follow-up can help distinguish each learner’s contribution.

Pair work can lower the pressure of speaking to the whole class, but it should not be the only evidence used for an individual grade. Provide clear roles and a brief individual reflection so quieter learners are not overlooked.

5. The live demonstration or practical explanation

In a workshop, laboratory, studio or vocational course, ask learners to perform a task while explaining key decisions. They might configure a device, interpret a measurement, prepare a material, debug a small program or demonstrate a safety procedure. The teacher observes both the process and the learner’s explanation.

This format assesses performance in context. It can be more authentic than asking students to describe a practical skill in an essay, but it requires suitable equipment, enough observation time and a clear standard for what counts as competent performance.

A simple rubric: score reasoning, not speaking style

Oral assessment becomes more defensible when learners know what the teacher is evaluating. A short rubric can use four dimensions, each scored on a four-point scale:

  • Accuracy: Is the explanation factually and conceptually sound?
  • Reasoning: Can the learner explain why a method, interpretation or decision was chosen?
  • Application: Can the learner transfer the idea to a changed example or a new condition?
  • Reflection and correction: Can the learner notice uncertainty, respond to feedback or revise an answer when new information appears?

Define what each score means before the assessment. For example, a score of 4 might indicate an accurate explanation supported by relevant reasoning and successful transfer; a score of 2 might indicate partial understanding with gaps that require prompting. Use subject-specific examples so that different teachers interpret the criteria consistently.

Do not quietly turn confidence, accent, speed, eye contact or extroversion into proxies for knowledge. A fluent speaker can be wrong; a hesitant learner can understand the material. If oral communication itself is a learning outcome, assess it explicitly and separately from subject knowledge.

Fairness and accessibility are part of validity

Oral assessment can disadvantage learners who experience speaking anxiety, have speech or hearing differences, use an additional language, need more processing time, or communicate more effectively through another mode. A format that appears resistant to AI but measures these unrelated factors poorly is not a valid solution.

Use these safeguards:

  • Publish the criteria and question themes: learners should know the knowledge and reasoning being assessed, even if the exact follow-up question is not disclosed.
  • Offer reasonable adjustments: allow additional processing time, assistive communication, written prompts, a quieter setting or an agreed alternative mode where needed.
  • Separate subject mastery from oral fluency: grade spoken communication only when it is genuinely part of the intended outcome.
  • Keep high-stakes decisions multi-source: combine oral evidence with written, practical and longitudinal evidence rather than relying on one short conversation.
  • Protect privacy: explain whether a conversation is recorded, why any recording is needed, who can access it and when it will be deleted. Do not record by default if observation and rubric notes are sufficient.
  • Check consistency: use shared prompts and sample responses, and moderate a sample of assessments with another teacher where feasible.

A 2026 letter in Educational Researcher directly addresses the equity, validity and scale problem in oral assessment. Hu and Hashim recommend separating language production from disciplinary reasoning, providing targeted accommodations, standardizing examiner behaviour and using “viva-lite” oral verification as a supplement to selected tasks. These proposals reinforce that oral assessment should be designed for fairness and reliability, not merely as an anti-cheating response. See Hu and Hashim (2026).

The OECD’s July 2026 policy paper on responsible GenAI adoption in higher education identifies academic integrity, equity, data protection, reliability and the development of student knowledge and skills as important policy concerns. Those concerns apply when institutions redesign assessment as well as when they procure AI tools.

Should AI be excluded from an oral assessment?

That depends on the learning objective. If the purpose is to check whether a learner can recall a foundational concept independently, the assessment may reasonably be conducted without AI. If the purpose is to assess professional judgement while using AI, banning the tool would remove part of the real task. The policy should state what is permitted before the assessment begins.

For an AI-permitted task, ask learners to explain how they framed the problem, which output they accepted or rejected, what they verified and where human judgement remained necessary. For an AI-restricted task, provide a clear reason and a consistent process. In either case, avoid treating a detector score or an impression of “AI-like” language as proof of misconduct.

Research on AI-supported assessment also points to the importance of teacher judgement. A 2026 article in the British Journal of Educational Technology examines how generative AI can be integrated into formative assessment while preserving teacher agency and professional judgement. A peer-reviewed multi-institutional study in Communications of the Association for Information Systems presents an implementation blueprint for interactive oral assessments built around preparing learners, preparing assessors and preparing processes. Its authors argue that preparation is central to equity, engagement and feasibility; see Webb and Galamba (2026) and Richter et al. (2026).

Researchers have also begun testing hybrid AI-supported oral assessment. The 2026 IEEE EDUCON paper “EvalIA: Towards a Hybrid AI-Supported Platform for Oral Performance Assessment” reports an early prototype and initial validation across five presentations. The reported agreement varied by criterion, so the work should be treated as an early technical and pedagogical exploration—not evidence that automated oral scoring is ready to replace teachers. Human review remains essential.

A two-week pilot for a school or training provider

A small pilot can test whether oral assessment adds useful evidence without redesigning an entire course.

  1. Days 1–2: Choose one learning outcome. Select a concept, reasoning skill or practical competency that learners should be able to explain or demonstrate. Decide whether AI is permitted.
  2. Days 3–4: Write a short rubric. Define accuracy, reasoning, application and reflection. Prepare a small set of equivalent prompts and follow-up questions.
  3. Days 5–7: Run low-stakes checks. Assess a small sample of learners, provide feedback and note where the prompts reveal understanding or create confusion.
  4. Days 8–10: Review fairness and consistency. Ask learners about clarity and pressure. Check whether language fluency, confidence or accessibility needs affected the evidence. Compare scoring between teachers if possible.
  5. Days 11–14: Compare with other evidence. Look at written work, practical performance and later recall. Keep the format only if it adds useful information and can be delivered fairly within available time.

Do not interpret a successful pilot as proof that oral assessment is suitable for every age group, subject or high-stakes examination. It is a way to test a local design before scaling it.

How oral assessment fits a wider assessment strategy

Oral checks should complement—not replace—good written assessment, retrieval practice, project work and feedback. Prowad’s guide to AI assessment design in higher education discusses broader changes to assessment tasks. The article on AI and student memory explains why learners still need opportunities to retrieve knowledge rather than simply recognise a generated answer. For schools evaluating tools used in these activities, see the evidence checks for AI learning tools.

The wider lesson is that assessment should make the intended learning visible. Sometimes that means a written argument; sometimes it means a live demonstration, a short explanation or a conversation about a learner’s decisions. The right format depends on what students are meant to know and do.

Conclusion: make understanding visible without making assessment unfair

Oral assessment in the AI era is useful because it gives teachers another way to observe reasoning, application and response to follow-up questions. It is not an AI detector, a guarantee of independent learning or a universal replacement for essays and projects.

Start with a clear learning outcome, use a transparent rubric, offer accessibility adjustments and combine oral evidence with other forms of assessment. If AI is allowed, assess the learner’s judgement about its output; if it is not, explain the boundary and apply it consistently. The goal is not to make assessment harder to outsource at any cost. It is to make the evidence of learning more meaningful, fair and useful for teaching.

References

Posted on — Leave a comment

AI Monitoring of Teachers: 7 Safeguards for Schools

Teacher working at a desk with a laptop and notes in a classroom

AI monitoring of teachers is moving from an abstract workplace-technology debate into a practical question for schools, universities and professional training providers: when does automated feedback help educators improve, and when does it become intrusive performance surveillance?

The distinction matters. An AI system may summarize a lesson, help a teacher reflect on questioning techniques or identify a topic learners found difficult. A system that continuously scores a teacher’s pauses, wording, response speed or classroom silence—and sends risk labels to managers—does something different. It turns selected signals into judgments about a complex human activity.

Recent reporting has made that tension visible. On 28 September 2026, The Guardian reported that instructors at UK training company Multiverse described stress and anxiety after an AI system began analysing lesson transcripts and flagging perceived performance concerns. The company said the system supports managers and does not write formal performance reviews. The accounts are reported allegations, not an independent evaluation of the system’s accuracy or effects.

For education leaders, the useful question is not simply whether AI can analyse a lesson. It is whether the monitoring purpose is justified, the evidence is valid, the data use is fair, and educators can challenge an incorrect interpretation.

Why AI monitoring of teachers is becoming a governance issue

AI can process far more text or audio than a human observer can review. That makes it attractive for quality assurance in online tutoring, apprenticeship programmes, teacher development and large training organisations. A dashboard may appear to offer consistent coverage where human observation is occasional.

But coverage is not the same as validity. A transcript may reveal whether a particular phrase appeared; it cannot reliably establish on its own why a teacher used it, whether a pause was productive, whether a learner’s silence signalled confusion, or whether an instructor deliberately departed from a script to meet an individual need.

The broader trend extends beyond education. On 28 October 2026, Reuters reported that Scale AI disputed privacy complaints concerning alleged monitoring of freelance AI-training workers. Those complaints concern a different workplace and remain allegations, but they illustrate the growing scrutiny of systems that convert workers’ digital traces into management signals.

The OECD’s 2026 report on reimagining teaching places professional autonomy, trust and collaboration alongside the use of AI as central issues for the future of teaching. Monitoring should be judged against those goals, not just against how many sessions a system can process.

What AI systems can measure—and what they cannot safely infer

Depending on their design, AI monitoring tools may analyse lesson transcripts, speaking patterns, adherence to a script, response timing, participation signals or selected behaviours. These features can sometimes help a coach locate a moment for closer review. The risk begins when a proxy is treated as a direct measure of teaching quality.

  • Filler words are not a complete measure of expertise. A teacher can speak fluently and still explain a concept poorly; a thoughtful teacher may use pauses or hedging while modelling uncertainty.
  • Silence is ambiguous. It may indicate confusion, reflection, independent work, a technical issue or a deliberate wait-time strategy.
  • Script adherence is not the same as responsiveness. A useful lesson may require changing an example, slowing down or answering an unexpected question.
  • A confidence score is not proof. A model’s numerical confidence should not be presented as a calibrated probability that a teacher performed well or badly unless that claim has been independently validated.

Research on AI in classroom management provides a warning about the evidence base. A 2025 systematic review of 104 studies found that ethical issues were discussed in only 22% of the reviewed studies and privacy-preserving measures were implemented in 13%. The review concerns classroom-management research rather than every teacher-monitoring product, so its figures should not be treated as a direct audit of workplace monitoring. They do, however, show why institutions should ask for evidence about privacy and ethics instead of assuming that technical capability guarantees responsible use. See the review in Computers and Education: Artificial Intelligence.

Related research on digital surveillance in blended higher education has also documented tensions between institutional oversight, trust and teacher–student relationships. That study does not establish that every monitoring system causes harm, but it reinforces the need to assess how surveillance changes professional behaviour and classroom relationships, not only how accurately software classifies data. Read the open-access study in Postdigital Science and Education.

Seven safeguards for schools and training providers

1. Define a narrow, educational purpose

Start with a specific question: for example, can optional transcript summaries help instructors notice that their explanations of one concept are consistently unclear? Avoid vague goals such as “measure teacher quality” or “identify low performers.” Record what the system is intended to improve, what it must not be used for, and who is accountable for the decision.

Before buying a tool, compare it with less intrusive options such as peer observation, learner feedback, voluntary self-reflection or targeted coaching. If a simpler method can achieve the same purpose, continuous monitoring may not be justified.

2. Tell educators what is collected and how it is used

Give staff clear, accessible information before a pilot begins. Explain whether audio, video, transcripts, chat messages or learner data are captured; which model analyses them; who sees the output; how long records are retained; whether a vendor can reuse data; and whether results can influence appraisal, promotion or contract renewal.

Involve teachers, trainers, staff representatives and data-protection specialists in design decisions. Consultation is not a substitute for a lawful basis, but it can reveal practical problems that managers and vendors may miss.

3. Minimise data and retention

Collect only what is necessary for the stated purpose. If the goal is to improve lesson explanations, a carefully selected transcript excerpt may be enough; continuous video, facial analysis or unrelated device activity may add intrusion without adding educational value. Restrict access, set deletion periods, secure vendor contracts and prohibit secondary uses that have not been clearly authorised.

The UK Information Commissioner’s Office explains that worker monitoring must be lawful and fair, and that excessive monitoring can undermine privacy and mental wellbeing. Its guidance on data protection and monitoring workers recommends a clear purpose, proportionality, transparency and consideration of a data protection impact assessment.

4. Validate outputs in real teaching contexts

Do not rely on a vendor demonstration or a single aggregate accuracy score. Test the system across subjects, age groups, accents, languages, class sizes, online and in-person formats, and different teaching styles. Have experienced educators independently review a sample of flagged and unflagged sessions. Record false positives, missed issues and differences between groups.

Ask vendors to explain the training data, known limitations, evaluation methods and conditions under which the system should not be used. If a product cannot explain why it flags a session or cannot provide meaningful evidence of validity, do not use its scores for consequential decisions.

5. Make human oversight meaningful

A manager should not simply approve an AI-generated rating. Reviewers need access to the relevant context, time to inspect the evidence, authority to disagree with the system and a process for asking the educator for their explanation. A score should be a prompt for inquiry, not a verdict.

The ICO’s guidance on monitoring tools that use solely automated processes stresses meaningful human involvement where automated processing informs significant decisions about workers. The exact legal requirements depend on jurisdiction and use case, so institutions should obtain appropriate advice before deployment.

6. Pilot for learning, not punishment

Run a limited pilot with a defined end date and agreed evaluation criteria. At first, use outputs for voluntary reflection or coaching rather than employment decisions. Compare the system’s observations with peer review and learner evidence, and ask teachers whether the feedback is accurate, useful and respectful.

Measure unintended effects as well as efficiency: anxiety, workload, changes in teaching style, willingness to answer difficult questions, learner participation and time spent contesting flags. Pause the pilot if the tool encourages performative compliance, produces persistent unexplained errors or reduces attention to learners.

7. Provide access, correction and appeal

Educators should be able to see the information about them, understand the reason for a flag, correct inaccurate records and challenge a conclusion before it affects them. Keep an audit trail of model outputs, human changes and final decisions. Set an independent route for complaints and review the system regularly after updates.

These controls also help distinguish developmental feedback from formal performance management. If an organisation intends to use monitoring data in high-stakes decisions, that use needs a separate assessment rather than being quietly added to a coaching tool after the pilot.

What the EU AI Act means for worker monitoring

The EU AI Act lists certain AI systems intended for employment, workers’ management and access to self-employment as high-risk, including systems intended to monitor or evaluate workers’ performance and behaviour. The classification depends on the system’s intended purpose and the Act’s conditions and exceptions; it should not be reduced to the claim that every classroom analytics tool is automatically high-risk.

Education providers operating in or serving the EU should review the relevant provisions in Regulation (EU) 2024/1689, especially Annex III, alongside applicable employment and data-protection rules. Organisations elsewhere should check their own legal framework. This article is an educational overview, not legal advice.

A practical 30-day implementation plan

  1. Week 1 — Define the purpose. Write a short impact statement, map the data collected, identify alternatives and consult educators.
  2. Week 2 — Test and challenge. Use a small, representative sample; compare AI flags with independent educator review; document errors and uncertainty.
  3. Week 3 — Run a limited coaching pilot. Give participants access to outputs, a human contact and a clear way to correct or contest results. Do not use pilot scores for disciplinary decisions.
  4. Week 4 — Review the evidence. Compare educational usefulness, false-positive rates, staff experience, privacy risks and total workload. Continue only if the benefits are clear and the safeguards work.

For a broader framework, connect this process to four models of teacher–AI collaboration, the site’s guide to building an AI use policy, and its analysis of AI teacher-training competencies. Those resources can help institutions place monitoring within a wider strategy for responsible AI adoption rather than treating it as a stand-alone management solution.

Frequently asked questions

Can AI reliably evaluate teaching quality from a transcript?

A transcript can support a narrow review, but it does not capture every relevant feature of teaching. It may omit non-verbal context, learner needs, subject difficulty and reasons for adapting a lesson. Use it as one source of evidence, not a complete evaluation.

Is AI monitoring of teachers legal?

It depends on where the organisation operates, what data is collected, the purpose, the level of intrusion and how outputs are used. Data-protection and employment rules may require transparency, proportionality, a lawful basis, impact assessment and meaningful human review. Obtain jurisdiction-specific advice.

Should AI-generated scores affect a teacher’s employment?

Do not use scores as an automatic verdict. Before any consequential use, validate the system, disclose its role, provide access to evidence and appeal, ensure meaningful human decision-making, and assess applicable legal obligations. In many settings, a developmental coaching purpose is safer and more educationally defensible than continuous punitive scoring.

The bottom line

AI monitoring of teachers should be judged by whether it improves teaching and learning without undermining professional trust, privacy or autonomy. Schools and training providers should begin with a narrow purpose, collect less data, validate outputs with educators, preserve meaningful human oversight and give staff a genuine right to challenge errors. If a tool cannot meet those conditions, more monitoring is not the same as better education.

Image credit: Vitaly Gariev via Unsplash.

Posted on — Leave a comment

Generative AI Learning Outcomes: What a 2026 Meta-Analysis Really Shows

Teacher reviewing research and lesson notes on a laptop at a classroom desk

Short answer: A peer-reviewed meta-analysis published on 21 October 2026 found a positive average association between generative AI-supported instruction and students’ learning-related outcomes. But its headline effect is not a guarantee that an AI tool will help in every classroom. The same paper reports substantial variation between results and a prediction interval that includes no benefit. For schools and training teams, the useful question is not “Does AI work?” but “For which learners, task, teaching design and assessment does it work—and how will we know?”

This guide explains what the new evidence can support, what it cannot establish, and how educators can translate it into a sensible evaluation plan. It also distinguishes learning with AI from learning that students can demonstrate independently.

What the October 2026 meta-analysis examined

Khodjaev, Masalimova, Chistyakov and Ay published “A meta-analysis of the effects of generative artificial intelligence on learning, cognitive, and linguistic outcomes” in Frontiers in Education on 21 October 2026. The researchers synthesized 68 effect sizes from 58 peer-reviewed primary studies, representing 6,941 participants.

The review focused on three outcome families:

  • Learning outcomes: academic performance, comprehension, retention and transfer.
  • Linguistic outcomes: writing, speaking, reading, vocabulary, grammar and pronunciation.
  • Cognitive outcomes: measures such as memory, attention, reasoning, cognitive load and problem-solving.

The researchers searched Web of Science and Scopus in May 2026, screened studies against eligibility criteria and used a three-level random-effects model with cluster-robust variance estimation. That matters because some primary studies reported more than one relevant outcome; those results are related, not wholly independent observations.

The evidence base is not evenly distributed across contexts. Around 73.5% of the included effect sizes came from higher-education or adult samples, while primary-school samples accounted for 10.3%. China and Taiwan contributed a substantial share of the studies. The findings are informative, but they should not automatically be generalized to every age group, language, curriculum or education system.

What does the headline effect size mean?

The authors reported a pooled standardized effect of Hedges’ g = 0.864, with a 95% confidence interval from 0.720 to 1.009. In the sample of studies included, the average result favored GenAI-supported learning. Hedges’ g expresses a difference in standardized units; it is not an 86.4% improvement, a percentage-point gain, or a promise that a student will receive a higher grade.

A pooled estimate is useful because individual studies can be small, narrow or inconsistent. Combining results can provide a more stable estimate of the average pattern across the included evidence. Yet the average is only one part of the story. The range of results and the quality of the underlying studies matter just as much when deciding whether to adopt a tool.

For example, a chatbot that gives step-by-step hints during practice may affect learning differently from a tool that writes an essay, summarizes a reading or generates language exercises. Even when two interventions use the same underlying model, the instructional task, amount of guidance, teacher involvement and assessment method can change the result.

The most important caveat: effects varied widely

The review reported substantial heterogeneity, with I² around 88%. In plain language, the differences among study results were much larger than would be expected from sampling error alone. The studies were not all estimating one identical, universal effect.

The authors also reported a 95% prediction interval from −0.213 to 1.942. A confidence interval around a pooled average describes uncertainty about that average. A prediction interval asks a different question: how widely might the true effect vary in a new, comparable setting? Here, the interval crosses zero, meaning a future implementation could plausibly show little or no benefit—and, in some circumstances, a negative result—even though the overall average was positive.

This is not a contradiction. A treatment can have a favorable average while working better under some conditions than others. It is a reason to evaluate a specific educational use case rather than treating “AI in education” as a single intervention.

It also explains why a school should avoid making procurement decisions based on one impressive number. A strong result in language learning or a university course does not prove that the same product will improve primary mathematics, vocational training or independent reading.

How publication bias could affect the estimate

The authors tested whether the observed evidence showed signs of small-study effects. Egger’s regression indicated funnel-plot asymmetry (p = .002), and PET–PEESE adjustments suggested that the underlying effect might be appreciably smaller than the headline estimate—roughly g = 0.26 to 0.45, depending on the estimator.

These tests are warning signals, not a definitive measurement of how much bias exists. Funnel-plot asymmetry can have more than one explanation, and statistical corrections rely on assumptions. The review’s trim-and-fill procedure did not impute missing studies, while the other diagnostics still suggested caution. Taken together, the results support neither dismissing the review nor repeating its largest number without qualification.

A practical reading is: the evidence points toward possible benefits, but the magnitude may be overstated and is not yet sufficiently predictable across settings. Independent replications, larger samples, preregistered studies and transparent reporting of null results would help clarify the picture.

Why other 2026 reviews report different effects

Meta-analyses can produce different pooled estimates without one necessarily being wrong. Their research questions, populations, outcome definitions, dates, inclusion criteria and comparison groups differ.

  • Higher education specifically: A May 2026 three-level meta-analysis by Fan and colleagues synthesized 132 effect sizes from 36 studies and 7,229 participants. It reported a medium overall effect (g = 0.499) and found stronger results in collaborative and blended learning designs. Its scope was higher education, not the same mix of learning, cognitive and linguistic outcomes as the October review. Read the higher-education meta-analysis.
  • AI literacy classes for school-age learners: A meta-analysis published in the Journal of Computer Assisted Learning in August 2026 examined 16 articles and 57 effect sizes on whether teaching students about AI improves AI literacy. It reported a positive average effect (g = 0.892). This is a different question from whether students learn subject content with a generative AI assistant. Read the K–12 AI-literacy review.
  • AI applications more broadly: A February 2026 second-order meta-analysis combined 19 earlier meta-analyses and reported a moderate average effect (ES = .67). Because it covered AI applications and earlier reviews more broadly, it should not be compared as if it were a direct replication of the October GenAI analysis. Read the second-order meta-analysis.

These estimates are not a leaderboard for AI products. They are summaries of different bodies of evidence. Before comparing effect sizes, check who was studied, what counted as learning, how AI was used, what the control group did and whether the outcome was measured while the AI tool remained available.

What the evidence means for schools and training providers

The strongest practical response is to define a learning problem before choosing a tool. An AI feature may save preparation time without improving student learning; it may improve the quality of a draft while leaving students unable to explain the underlying idea. Those are different outcomes and should be measured separately.

1. Set one observable learning goal

Replace a broad goal such as “use AI to improve learning” with a testable target: for example, learners will explain a concept in their own words, solve a new problem, revise a weak argument or recall key ideas one week later. A clear outcome makes it easier to decide whether AI is appropriate.

2. Decide what the learner must still do independently

Identify the thinking that must not be outsourced. Depending on the subject, that may include retrieving facts from memory, choosing a method, constructing an argument, interpreting evidence or diagnosing an error. AI can provide hints, counterexamples and feedback while leaving those decisions with the learner.

3. Compare against a meaningful alternative

Do not compare an AI-supported class only with “nothing.” Compare it, where feasible, with a credible alternative such as teacher feedback, worked examples, peer discussion or structured practice. If AI performs similarly to a simpler and cheaper method, the institution should consider whether the additional complexity is justified.

4. Measure both assisted performance and independent learning

Collect evidence while students use the tool and, when relevant, after it is removed. A polished answer produced with AI is not the same as durable knowledge. Short quizzes, transfer tasks, oral explanations, delayed recall and revisions with reasons can reveal whether learners have internalized the material.

5. Monitor who benefits and who is left behind

Look for differences by prior knowledge, language proficiency, accessibility needs and access to devices. Check whether examples are accurate and inclusive, whether the system invents facts or citations, and whether students can recognize and correct errors. Avoid entering identifiable learner data into an unapproved system.

A simple evaluation checklist before adoption

Use these questions in a pilot rather than relying on product demonstrations or vendor claims:

  1. Purpose: What specific learning outcome should improve?
  2. Mechanism: How is the AI expected to help—hints, practice, feedback, explanation, language support or something else?
  3. Comparison: What existing method will serve as the benchmark?
  4. Evidence: What will be measured, when will it be measured, and will some assessment happen without AI?
  5. Quality and safety: How will educators check accuracy, privacy, accessibility and age appropriateness?
  6. Equity: Do learners have comparable access, and are the benefits distributed fairly?
  7. Decision rule: What result would justify continuing, changing or stopping the pilot?

Keep the pilot narrow enough to learn from. Record the task, model or product version, prompts or scaffold, duration, teacher role, learner group and assessment conditions. Without those details, a positive or negative result will be difficult to interpret or reproduce.

What teachers and professional-development leaders should do next

Professional development should focus on instructional judgement, not only prompt-writing. Teachers need practice selecting tasks suited to AI support, checking outputs, designing assessments that reveal student thinking and explaining why they accepted or rejected a suggestion. Institutions can connect this work to AI teacher-training competencies and the five-step AI integration framework already discussed on Prowad.

For a broader introduction to the evidence on learning and assessment, see our guide to generative AI in education research. For a practical way to assess the tools themselves, use the seven evidence checks for AI learning tools. If a tool mainly produces feedback, our analysis of AI feedback versus actual learning explores why feedback quality and learning gains should not be treated as interchangeable.

The OECD’s 2026 report Reimagining Teaching in an Accelerating World also emphasizes the changing role of teachers as AI use spreads. The institutional task is not simply to increase adoption; it is to build the professional knowledge, safeguards and evaluation capacity needed to use AI purposefully.

Frequently asked questions

Does the new meta-analysis prove that generative AI improves learning?

No. It reports a positive average effect across the included studies. High heterogeneity, a prediction interval crossing zero and signs of small-study effects mean results are not guaranteed in a new context.

Is Hedges’ g = 0.864 an 86.4% improvement?

No. Hedges’ g is a standardized effect size. It describes the average difference in standard-deviation units, not a percentage increase, a grade-point change or the share of students who benefit.

Should every school introduce AI because the average effect is positive?

No. Schools should first identify the learning need, compare AI with credible alternatives, check privacy and accessibility, and run a focused pilot with meaningful assessments.

What is the difference between AI literacy and learning with AI?

AI literacy means understanding, evaluating or using AI responsibly. Learning with AI means using an AI system to support another learning goal, such as language development or subject knowledge. Evidence for one outcome should not be assumed to prove the other.

Conclusion: treat the average as a starting point, not a promise

The October 2026 meta-analysis adds valuable evidence that generative AI can support learning-related outcomes on average. Its most useful lesson, however, is methodological: the average effect is not the effect every school should expect. Differences among tasks, learners, comparison methods and study quality matter.

For educators, the responsible path is to start with a clearly defined learning objective, keep essential thinking visible, compare AI with a credible alternative and measure what learners can do independently. The question is not how much AI a school can deploy. It is whether a carefully designed use helps learners understand, remember, transfer and apply what they are taught.

Evidence note: This article interprets the published studies linked above; it is not a new systematic review. Effect-size estimates should be read in the context of each review’s eligibility criteria and limitations.

Posted on — Leave a comment

When Should Teachers Use AI? A Human-First Sequence for Lesson Design

Laptop and planning materials on a classroom desk for teacher lesson design

Short answer: Teachers should often begin a lesson-design task without generative AI, then introduce AI to challenge, expand or test their thinking—not automatically to produce the first complete answer. A 2026 study of pre-service teachers offers a useful clue: AI was most effective when it followed initial human-only design work and was paired with collaborative inquiry and reflective learning analytics. The findings are promising, but they do not prove that delaying AI by itself improves teaching in every context.

For schools and teacher-education programmes, the practical question is not simply whether to use AI. It is when to use it, what thinking should happen first, and how educators can tell whether the final design is better.

What the 2026 study found

In August 2026, Yang and colleagues published “Fostering preservice teachers’ design thinking by integrating generative AI and analytics-supported reflective assessment in a collaborative inquiry environment” in Computers & Education. The study followed 110 pre-service teachers enrolled in a semester-long educational technology course at a teacher-education university in central China. Participants worked in a collaborative Knowledge Building environment that combined inquiry, generative AI and analytics-supported reflection.

The design deliberately positioned AI as a cognitive and reflective partner rather than a solution provider. Students first had opportunities to develop ideas through human-led work; AI was introduced strategically later in the process. The researchers examined a design-thinking scale, successive instructional-design artefacts and 1,305 online discourse notes.

The reported pre–post design-thinking score rose from 5.15 to 5.25. The change was statistically significant, but the effect size was small (Cohen’s d = 0.21). The study also found gains in problem discovery and definition, alongside a shift towards more integrated, iterative design practices, particularly prototyping and testing. The authors reported that GenAI was most effective after human-only design efforts.

Source: Yang et al. (2026), Computers & Education, 249, article 105602. A related conference poster is available from the International Society of the Learning Sciences.

Why the timing of AI use may matter

Generative AI can quickly produce lesson objectives, activities, examples and assessment questions. That speed is useful, but it can also hide the thinking that teachers need to practise: identifying the actual learning problem, deciding what evidence would show understanding, anticipating misconceptions and making trade-offs for a particular class.

If a teacher accepts a polished first draft before defining the learning problem, the output can become the frame for every later decision. The teacher may spend time editing an answer whose underlying assumptions were never examined. Starting without AI creates a visible baseline: the teacher can identify what they already understand, where they are uncertain and which decisions need outside challenge.

Introducing AI later changes its role. Instead of asking, “Write my lesson,” the teacher can ask, “What misconception have I missed?”, “Which part of this activity does not align with the learning objective?” or “Offer two alternative explanations for learners who struggle with this concept.” Those prompts support critique and comparison rather than passive acceptance.

This interpretation is consistent with a 2026 critical review of 20 studies on generative AI in teacher professional development. Shenoy and Saarela identify functional, cognitive, social and reflective affordances, while highlighting gaps in explicit training for critical evaluation, ethical reasoning and verification. The review is a synthesis of a still-developing evidence base, not proof that one sequence works for all teachers.

Further reading: Shenoy and Saarela (2026), “A critical review and actionable framework for integrating generative AI into teacher professional development”.

What the study does—and does not—prove

The results should be read carefully. The intervention combined several elements: collaborative inquiry, strategically delayed GenAI use and analytics-supported reflective assessment. It was not a simple experiment in which one group used AI immediately and an otherwise identical group used it later. We therefore cannot attribute the observed change to timing alone.

  • It suggests: a structured process that gives teachers room to frame a problem before AI assistance can support design thinking.
  • It does not establish: that delaying AI will always improve lesson quality, student attainment or teacher performance.
  • It does not mean: teachers should avoid AI during brainstorming or that AI-first work is always harmful.
  • It does mean: schools should test the sequence against learning goals and examine the quality of the resulting work, not merely how quickly a draft is produced.

The small effect size is another reason to avoid exaggerated claims. The study is useful as a design signal and a basis for local experimentation, not a universal rulebook.

A four-step human-first workflow teachers can try

1. Frame the learning problem before opening an AI tool

Spend five to ten minutes writing the intended learning outcome, the evidence that would demonstrate it and two likely misconceptions. Identify the learners, prior knowledge, curriculum constraints and any accessibility needs. This short human-only phase gives the teacher a clear point of view against which AI suggestions can be judged.

For example, instead of starting with “Create a lesson on fractions,” write: “Learners should explain why two fractions with different numerators can represent the same quantity, and justify their reasoning using a diagram.” That statement defines a learning problem rather than a content topic.

2. Ask AI to challenge the draft, not replace it

Once a first idea exists, use AI for a bounded purpose. Ask it to identify a misconception, suggest a contrasting example, propose a question that reveals shallow understanding or point out where an activity may not match the objective. Ask for alternatives and reasons, not a single authoritative answer.

A useful prompt is: “Review this lesson idea as a critical teaching colleague. Identify two likely misconceptions, one accessibility barrier and one mismatch between the objective and the assessment. Explain the reasoning for each suggestion. Do not rewrite the lesson yet.”

3. Compare every suggestion with subject knowledge and evidence

Teachers should verify factual claims, curriculum alignment, age appropriateness and the suitability of examples. AI can invent references, oversimplify a concept or recommend an activity that sounds engaging but measures the wrong skill. Reject suggestions that do not fit the learners or the available evidence. Never enter identifiable student information into a tool unless the institution has explicitly approved that use and the relevant privacy requirements are met.

4. Revise, then explain the decisions

After comparing the suggestions, revise the lesson yourself. Record which AI suggestions were accepted, adapted or rejected and why. That brief reflection turns AI use into a professional-learning activity: teachers practise making and defending decisions rather than simply producing a document.

How to check whether the workflow is helping

Do not evaluate the process only by minutes saved or by how polished the lesson plan looks. A school or teacher-education programme can use a short rubric before and after a trial:

Indicator Evidence to look for
Problem definition Does the plan name a specific learning difficulty or misconception?
Alignment Do the activities and assessment measure the stated learning objective?
Quality of reasoning Can the teacher explain why key choices were made and which alternatives were rejected?
Iteration Does the final plan improve on the first draft in identifiable ways?
Verification and inclusion Are factual claims checked, student data protected and accessibility needs considered?

Where feasible, collect a first draft, a revised draft and a short reflection. Compare them using the same rubric. If teachers save time but the reasoning, alignment or accessibility of the lesson deteriorates, the workflow needs redesign. If the quality improves without excessive extra work, the sequence may be worth retaining. A small local trial cannot prove universal effectiveness, but it can inform a better decision than relying on enthusiasm or anxiety alone.

How teacher educators can build this into professional development

Teacher development should teach more than prompt-writing. Participants need opportunities to practise subject-specific judgement, test AI suggestions, discuss privacy and bias, and compare examples of weak and strong instructional alignment. A short workshop can model the four steps, but follow-up is important: teachers should try the process with a real lesson, bring their drafts back and discuss what changed.

Programme leaders can connect this approach with broader AI teacher-training competencies and the practical AI integration framework for educational institutions. Schools can also use our guide to measuring AI literacy beyond prompting to define the competencies teachers should demonstrate. For a wider view of how responsibilities can be divided between educators and tools, see our guide to teacher–AI collaboration in education.

Professional development should also be differentiated. A novice may need support checking outputs and protecting data; an experienced teacher may be ready to use AI to stress-test assessment design or compare alternative explanations. In both cases, the goal is not maximum AI use. It is better professional judgement and more purposeful learning design.

Frequently asked questions

Should teachers always create a lesson plan without AI first?

No. A human-first phase is a useful option when the goal is to practise problem framing, design judgement or independent thinking. For routine administrative tasks or when a teacher needs accessibility support, earlier AI assistance may be appropriate. The sequence should match the learning goal and the risks of the task.

Does delayed AI use improve student learning?

The cited study examined pre-service teachers’ design thinking in a combined collaborative-learning intervention. It does not directly establish that delayed AI use improves school pupils’ learning outcomes. More controlled research is needed to isolate the effect of timing and test it across subjects and learner groups.

What is the difference between using AI as an author and as a critic?

As an author, AI generates a substantial first draft. As a critic, it reviews a draft the teacher has already considered, offering alternatives, identifying possible gaps and raising questions. The second role makes the teacher’s initial reasoning visible and easier to compare with suggestions.

How can a school measure success?

Use a shared rubric to assess problem definition, alignment, reasoning, iteration and verification. Combine those measures with teacher reflections and, where appropriate, evidence from classroom implementation. Track time, but do not treat time saved as a substitute for learning quality.

Conclusion: let AI enter at the point where it adds value

The emerging evidence supports a practical principle: do not let the speed of generative AI decide the order of professional thinking. When the learning goal is to develop teachers’ design judgement, begin by framing the problem, bring AI in to challenge and extend the draft, verify its suggestions and reflect on the choices made. The 2026 study offers a promising example of this sequence, but its small effect and combined intervention call for careful interpretation.

The best question for a teacher is not “Can AI make this lesson for me?” It is “Which part of this task benefits from AI, which part requires my judgement, and what evidence will show that the final lesson is better?”

References

  • Yang, Y., Chen, L., Sun, D., Zhu, W., & Pang, S. (2026). Fostering preservice teachers’ design thinking by integrating generative AI and analytics-supported reflective assessment in a collaborative inquiry environment. Computers & Education, 249, 105602. https://doi.org/10.1016/j.compedu.2026.105602
  • Shenoy, P., & Saarela, M. (2026). A critical review and actionable framework for integrating generative AI into teacher professional development. Discover Education, 5, 570. https://doi.org/10.1007/s44217-026-01579-7
  • International Society of the Learning Sciences. (2026). Fostering preservice teachers’ design thinking… CSCL 2026 conference poster. Repository record
Posted on — 3 Comments

Teacher–AI Collaboration in Education: 4 Models Schools Can Use

Teacher working on a laptop in a classroom while planning teaching activities

Schools do not need to choose between “AI does the work” and “teachers do everything themselves.” A more useful question is how to divide a teaching task so that software handles a suitable part while educators retain the judgement, relationships and responsibility that make teaching work.

A chapter in the OECD’s Co-constructing Visions for the Future of Teaching, published on 19 October 2026, frames this as hybrid human–AI collaboration. It distinguishes replacement, complementation and augmentation, and argues that AI should be designed around educational practice rather than bolted onto it. This article turns that framework into four practical models schools can test—while separating an emerging design vision from evidence that has already been demonstrated.

Why teacher–AI collaboration is a design problem

AI tools are often evaluated as if the system alone produces the educational outcome. In a classroom, however, outcomes usually depend on a social and technical system: the tool, the teacher, the learner, the task, the curriculum and the conditions in which they interact.

The OECD chapter by education researcher Inge Molenaar argues that the relevant question is not simply whether an AI product improves a test score. Schools should examine how teacher and AI contributions fit together, whether the system reflects sound knowledge about learning, and whether the arrangement improves teaching without displacing important human responsibilities. The chapter also notes that research on how to design and implement teacher–AI collaboration remains limited. For a closer look at when AI should enter the lesson-design process, see our evidence review on when teachers should use AI. It is a future-oriented expert perspective, not a controlled trial proving that one collaboration model is best in every classroom.

This distinction matters because a fluent AI response can still be incorrect, misaligned with the curriculum or inappropriate for a particular learner. For related background, see Prowad’s guides to implementing AI in education and teacher AI competency frameworks.

Four models of teacher–AI collaboration

1. Full replacement for a narrow, bounded task

In a replacement model, an AI system performs a task that previously required a person. The OECD chapter gives examples such as an intelligent tutoring system allowing a learner to practise a defined skill without a teacher providing every step of support. In everyday school operations, a tool might also sort routine practice items or provide an initial correctness check against a fixed answer key.

This model is most defensible when the task is narrow, the expected output is easy to verify, the consequences of an error are limited and a clear route to human help remains available. It is much less appropriate for decisions about a learner’s ability, behaviour, wellbeing, progression or access to support.

School test: Start with one low-stakes, repetitive task. Compare the AI output with a teacher-checked sample, record the types of error, and specify when the task must be escalated to a person. Do not assume that success on one exercise means the system can safely handle a broader teaching responsibility.

2. Partial replacement: divide the task between teacher and AI

Partial replacement means the AI completes one component of a larger teaching task while the teacher handles the rest. For example, software may mark whether a maths answer is correct, while the teacher explains why a misconception occurred and helps the learner choose a strategy for the next attempt.

This model can reduce repetitive work without pretending that every part of feedback is equally automatable. Correctness checking, diagnosing a misconception, motivating a discouraged learner and deciding what to teach next are related but different tasks.

School test: Write down the task as separate steps. Assign the AI only the step it can perform reliably, then identify the human checkpoint. A teacher should be able to see enough of the AI’s output to challenge it, correct it or override it.

3. Complementation: add information to an existing teaching practice

In complementation, AI extends an existing practice by giving the teacher additional information or capacity. It does not simply take over a task; it helps the teacher do the task with better or more timely evidence.

For instance, an approved reading-support tool might summarise patterns in students’ recurring decoding errors across several practice sessions. The teacher still interprets those patterns, considers the child’s language and learning context, and decides whether to change instruction. The extra information may be useful, but it should not be treated as a diagnosis or as a complete picture of the learner.

This model is promising when the information is difficult to collect consistently by hand. It also raises questions about data quality, privacy, bias and whether the dashboard’s categories match the teacher’s professional understanding.

School test: Ask whether the additional information changes a real instructional decision. If teachers receive a dashboard but cannot interpret it, do not have time to act on it or do not trust its measurements, the extra data may add workload rather than value.

4. Augmentation: create a new teaching practice with AI

Augmentation goes beyond improving an existing task. Teacher and AI work together to make a new practice feasible—for example, exploring how a class might follow different practice sequences based on emerging patterns, while the teacher adjusts the plan using knowledge of students that the system cannot see.

Here, AI might help generate alternative explanations, propose differentiated practice or surface patterns across a large set of responses. The teacher decides whether those suggestions fit the learning objective, the curriculum and the students in front of them. The new practice should be treated as a design hypothesis to test, not as an automatic benefit of introducing AI.

School test: Define what the new practice makes possible, why it could not be delivered in the same way before, and what evidence would show that it improves learning or teaching. If the only outcome is more generated content, the innovation may not be educationally meaningful.

What the evidence says—and what it does not

The OECD chapter cites earlier task-level estimates suggesting that about 6% of teaching tasks could be replaced by AI, 22% are bottleneck tasks unlikely to be performed by AI in the near future, and 72% could involve some division of work between teachers and AI. These figures come from earlier OECD work on automation and skills. They should not be read as a current census of schools, a prediction that 72% of teachers will be replaced, or a guarantee that the remaining tasks can already be automated safely.

A broader systematic review and meta-analysis by Vaccaro, Almaatouq and Malone, published in Nature Human Behaviour in 2024, analysed 106 experimental studies and 370 effect sizes. Across the included experiments, human–AI combinations performed, on average, worse than the better of the human-alone or AI-alone conditions. The pattern varied by task: combinations tended to lose ground on decision tasks and showed more favourable results on content-creation tasks.

This is a warning against assuming that putting a person and an AI together automatically creates a better team. The meta-analysis covered multiple domains and is not direct proof about school teaching; the authors also noted substantial variation across studies. Its practical lesson is narrower: define the division of labour, understand each partner’s strengths, and test the combined process against relevant alternatives.

Research on formative assessment offers a related caution. A 2026 article in the British Journal of Educational Technology argues that generative AI may support personalised feedback and responsive teaching, but also stresses that the technology is fallible and that its value depends on teachers’ interpretation, professional judgement and pedagogical knowledge. This is a research-informed analysis, not evidence that every AI-supported assessment system improves outcomes.

A five-step pilot schools can run

  1. Choose a real teaching bottleneck. Start with a recurring task that consumes time or delays useful feedback. Avoid choosing a tool first and inventing a problem for it.
  2. Map the task into components. Separate data gathering, pattern recognition, explanation, decision-making, communication and follow-up. Identify which parts require context, empathy or professional accountability.
  3. Set a baseline before the pilot. Record the current time required, error rate, teacher workload and one or two learner outcomes relevant to the goal. Keep the comparison proportionate to the risk and scale of the pilot.
  4. Define the human checkpoint. Specify what the AI may do, what the teacher must review, what cannot be automated and how students or families can raise a concern. Do not enter identifiable student information into a tool unless the school has approved its data handling.
  5. Review and decide. Compare the pilot with the baseline. Look for benefits and unintended effects, including errors, extra verification work, unequal performance across groups and loss of teacher control. Continue, redesign or stop based on the evidence.

How to measure whether collaboration is working

Do not evaluate a teacher–AI workflow only by the number of minutes saved or the quantity of material generated. Those are operational measures, not proof of better teaching or learning.

  • Quality: Are outputs accurate, curriculum-aligned and useful after teacher review?
  • Learning: Can students explain or apply the idea independently, rather than only while the AI is helping?
  • Teacher workload: Does the workflow reduce total effort after checking, correcting and documenting AI outputs are counted?
  • Equity: Does it work across relevant language, disability, device and connectivity needs?
  • Agency and trust: Can teachers understand, question and override recommendations? Do students know when AI has been used?
  • Safety: Are privacy, retention, security, age-appropriateness and escalation procedures clear?

Schools can adapt Prowad’s evidence checks for evaluating AI learning tools to structure this review. For decisions involving institutional policy, the article Who Should Govern AI at Universities? explores the importance of oversight and professional rights.

Teacher professional learning must evolve with the system

Teachers need more than a list of prompts. They need to understand what the tool is designed to do, where it tends to fail, how its output should be checked, and how to decide which parts of a task should remain human-led. The UNESCO AI Competency Framework for Teachers provides a useful policy reference for developing teacher knowledge and skills around human-centred use, ethics, AI foundations and pedagogy.

Professional learning should be linked to real classroom practice. A team can co-design a small workflow, test it with suitable safeguards, examine examples of errors and revise the task division together. Teachers should be involved in tool selection and redesign rather than being asked to adapt unilaterally to a product chosen elsewhere.

Conclusion: design the partnership, do not assume it

Teacher–AI collaboration is not a single model. It may involve replacing a narrow routine, dividing a larger task, adding useful information to existing practice or creating a new learning activity. The right arrangement depends on the task, the quality of the system, the learners’ needs and the consequences of error.

The most responsible starting point is modest: choose one task, define the human and AI roles, measure a baseline, keep a clear human checkpoint and evaluate the combined workflow. AI should be judged by whether it helps teachers and learners achieve a meaningful educational goal—not by how much activity it can automate.

Sources and further reading